pgvector in Production: High-Scale Vector Search & Hybrid RRF in PostgreSQL
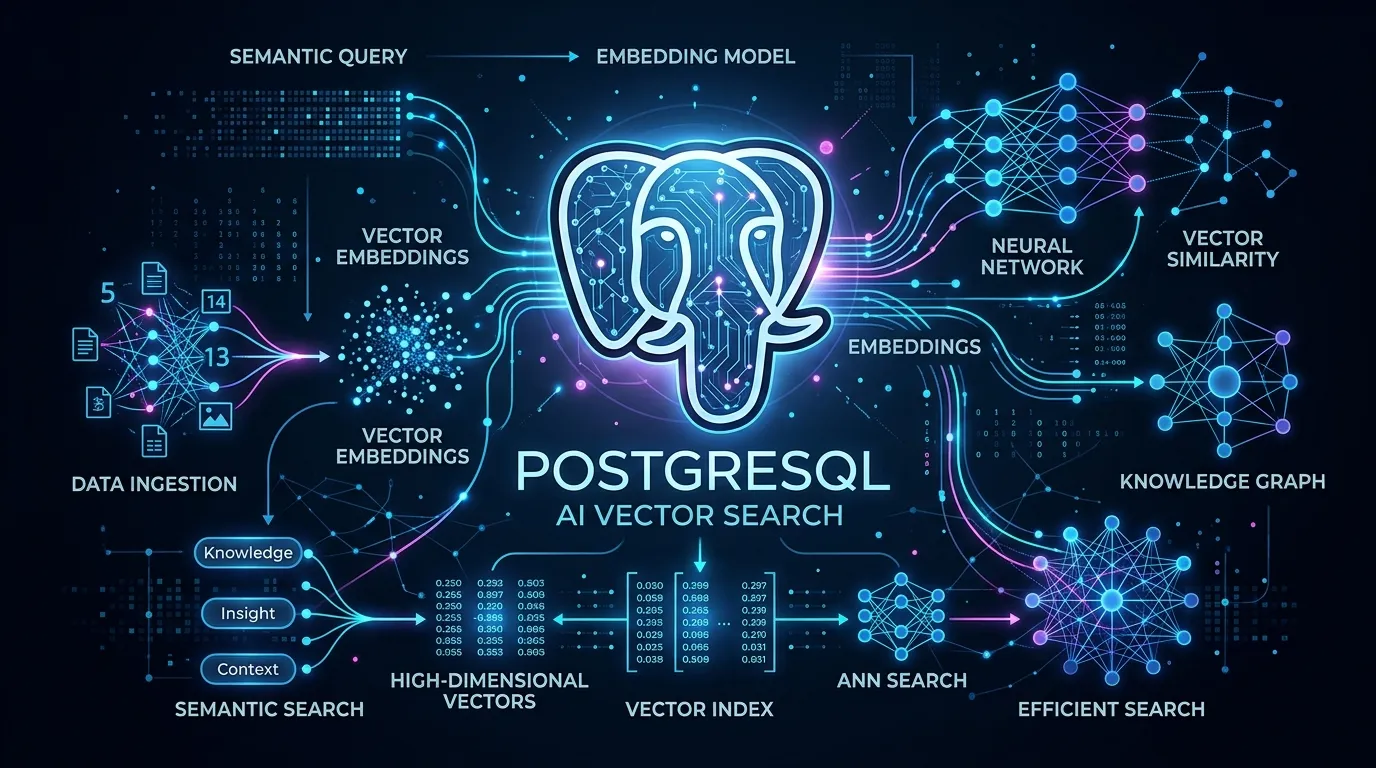

Table of Contents
In the early wave of generative AI and Retrieval-Augmented Generation (RAG) applications, engineering teams rushed to adopt specialized, standalone vector databases (such as Pinecone, Weaviate, Qdrant, and Milvus).
However, running a separate vector database alongside an existing relational database introduces severe operational friction: dual-write synchronization failures, eventual consistency lag, duplicated access-control policies, and painful distributed transaction rollbacks.
The release of pgvector (v0.7+) has established PostgreSQL as the dominant platform for production vector search. By storing high-dimensional embeddings directly inside standard PostgreSQL tables, you retain ACID transactions, familiar SQL semantics, robust backup tooling, and the ability to join vector queries against relational foreign keys in a single atomic query.
In this guide, we break down production indexing strategies (HNSW vs IVFFlat), optimize memory parameters, implement Hybrid Search using Reciprocal Rank Fusion (RRF) in pure SQL, and build a production Python client.
Why Consolidate on PostgreSQL? The Dual-Database Trap
Consider what happens when you separate your operational data from your vector embeddings:
[The Dual-Database Trap]
  User Action ──► Write to Primary Database (PostgreSQL)
                        │
                        ▼ (CDC Pipeline / Debezium / Celery Worker)
                  Dual-Write Lag & Potential Desync!
                        ▼
                  Write to Vector DB (Pinecone / Qdrant)

[The Unified pgvector Architecture]
  User Action ──► Write to PostgreSQL (Atomic Transaction)
                        ├── Relational Metadata (user_id, tenant_id, created_at)
                        └── High-Dimensional Vector (embedding vector(1536))
                  ✓ Zero Synchronization Lag
                  ✓ ACID Guarantees & Atomic Rollbacks
                  ✓ Unified Row-Level Security (RLS)
In pgvector, vector embeddings are simply a native data type. If a transaction fails or rolls back, your embeddings remain 100% consistent with your relational records.
Setting Up pgvector and Distance Operators
Install the extension and define your vector dimension size. Dimension sizes must match your embedding model exactly (e.g., 1,536 for OpenAI text-embedding-3-small, or 3,072 for text-embedding-3-large):
-- Enable the vector extension
CREATE EXTENSION IF NOT EXISTS vector;

-- Create production knowledge base table
CREATE TABLE document_chunks (
    id UUID PRIMARY KEY DEFAULT gen_random_uuid(),
    document_id UUID NOT NULL,
    tenant_id UUID NOT NULL,
    content TEXT NOT NULL,
    metadata JSONB DEFAULT '{}'::jsonb,
    embedding vector(1536) NOT NULL,
    created_at TIMESTAMPTZ DEFAULT NOW()
);
Choosing the Right Distance Metric
pgvector provides three distance operators:
<=>Cosine Distance: Measures the angle between vectors (values between 0 and 2, where 0 is identical). The standard metric for normalized text embeddings.<->Euclidean Distance (L2): Measures the straight-line spatial distance. Ideal when magnitude matters.<#>Negative Inner Product: Equivalent to dot product multiplied by -1. If your embedding model generates pre-normalized vectors (like OpenAI or Cohere), inner product is mathematically identical to cosine similarity but computes 20% to 30% faster because it skips the square-root normalization step!
Indexing Strategies: HNSW vs IVFFlat
Without an index, PostgreSQL performs an exact sequential scan across all vectors (O(n) flat search). While 100% accurate, flat scans become too slow for production once your table exceeds 50,000 vectors.
pgvector offers two Approximate Nearest Neighbor (ANN) indexing algorithms:
1. IVFFlat (Inverted File Flat)
- Divides vectors into clusters (lists) using k-means.
- Requires pre-populating the table with data before creating the index so the clustering algorithm has representative samples.
- Moderate build time and lower memory consumption, but search recall drops as new vectors are inserted.
2. HNSW (Hierarchical Navigable Small World) — Recommended for Production
- Constructs a multi-layer graph of connected vectors.
- Can be created on an empty table and continuously maintains high recall as new rows are inserted.
- Faster search queries (O(\log n)) and superior recall (98%+), at the cost of higher RAM usage and longer index build times.
-- Production HNSW Index Configuration
CREATE INDEX idx_document_chunks_hnsw_cosine
ON document_chunks
USING hnsw (embedding vector_cosine_ops)
WITH (m = 16, ef_construction = 64);
Tuning HNSW Parameters
m: The maximum number of bi-directional links per node (default: 16). Higher values (e.g., 24–32) improve recall for high-dimensional embeddings at the expense of memory.ef_construction: The size of the dynamic candidate list evaluated during index construction (default: 64). Increasing to 128 improves graph connectivity and query accuracy.hnsw.ef_search: Set at runtime to control query-time accuracy vs latency:
-- Tune per-session or per-query search depth
SET hnsw.ef_search = 100; -- Default is 40; higher values yield higher recall
Hybrid Search: Combining Dense Vectors with BM25 Keyword Search
Dense vector search is phenomenal at understanding conceptual synonyms ("automobile" matches "car"). However, vector search struggles with exact keyword lookups: part numbers, error codes (ERR_404_NULL), or proper names.
The industry gold standard is Hybrid Search via Reciprocal Rank Fusion (RRF), combining full-text search (tsvector) with semantic vector distance:
-- Hybrid Search using Reciprocal Rank Fusion in pure PostgreSQL
WITH semantic_search AS (
    SELECT id, content, RANK() OVER (ORDER BY embedding <=> '[0.012, -0.045, ...]') AS rank
    FROM document_chunks
    WHERE tenant_id = 'a1b2c3d4-e5f6-7890-abcd-1234567890ab'
    ORDER BY embedding <=> '[0.012, -0.045, ...]'
    LIMIT 20
),
keyword_search AS (
    SELECT id, content, RANK() OVER (ORDER BY ts_rank_cd(to_tsvector('english', content), query) DESC) AS rank
    FROM document_chunks, plainto_tsquery('english', 'database connection pooling') query
    WHERE tenant_id = 'a1b2c3d4-e5f6-7890-abcd-1234567890ab'
      AND to_tsvector('english', content) @@ query
    LIMIT 20
)
SELECT
    COALESCE(s.id, k.id) AS id,
    COALESCE(s.content, k.content) AS content,
    COALESCE(1.0 / (60 + s.rank), 0.0) +
    COALESCE(1.0 / (60 + k.rank), 0.0) AS rrf_score
FROM semantic_search s
FULL OUTER JOIN keyword_search k ON s.id = k.id
ORDER BY rrf_score DESC
LIMIT 10;
Production Python Integration with SQLAlchemy & pgvector
# db_vector_client.py
import os
from sqlalchemy import create_engine, select, text
from sqlalchemy.orm import declarative_base, Session
from pgvector.sqlalchemy import Vector

Base = declarative_base()

class DocumentChunk(Base):
    __tablename__ = 'document_chunks'

    id = Column(UUID, primary_key=True)
    tenant_id = Column(UUID, nullable=False)
    content = Column(Text, nullable=False)
    embedding = Column(Vector(1536), nullable=False)

def query_similar_chunks(tenant_id: str, query_embedding: list[float], limit: int = 5):
    engine = create_engine(os.getenv("DATABASE_URL"))
    with Session(engine) as session:
        # Cosine distance ordering using native pgvector operator
        stmt = (
            select(DocumentChunk)
            .filter(DocumentChunk.tenant_id == tenant_id)
            .order_by(DocumentChunk.embedding.cosine_distance(query_embedding))
            .limit(limit)
        )
        return session.scalars(stmt).all()
Frequently Asked Questions
How much RAM does pgvector require for 1,000,000 vectors?
For 1,000,000 vectors of 1,536 dimensions, the raw vector data occupies approximately 6 GB of storage. An HNSW index with m=16 adds approximately 2.5 GB of index data. For optimal sub-10ms query latency, ensure your PostgreSQL server has enough shared_buffers and RAM (at least 16 GB to 32 GB) to hold the entire HNSW index in memory.
Can pgvector scale to 50+ million vectors?
Yes. At 10M to 50M+ vectors, production teams use PostgreSQL Table Partitioning (e.g., partitioning by tenant_id or created_at year). Creating local HNSW indexes on individual partitions keeps each index small enough to fit within memory buffers.
How does pgvector compare to Pinecone in latency?
When the HNSW index fits in RAM, pgvector delivers query latencies of 4ms to 12ms, matching or outperforming dedicated cloud vector databases while eliminating internet network transit delays between your API server and third-party database endpoints.
You Might Also Like
Free In-Browser Developer Tools
Clean AI CLI logs, build cron expressions, decode JWTs, and calculate chmod permissions offline.
Related Articles
PostgreSQL Vacuum & Index Bloat: Detection, Mitigation, and Automated Tuning
Diagnose and eliminate PostgreSQL table and index bloat. Master autovacuum tuning formulas, pg_repack zero-downtime compaction, and MVCC visibility maps.
Read more
SQLite in Production: WAL Mode, High Concurrency, and Battle-Tested PRAGMAs
Master SQLite in high-throughput production environments. Learn Write-Ahead Logging (WAL), busy timeout tuning, concurrent reader/writer limits, and pragmatic benchmarks.
Read more
Vector Search at Scale: HNSW vs IVFFlat Indexing in pgvector and SQLite-vec
Compare HNSW and IVFFlat vector indexing algorithms in pgvector and sqlite-vec. Analyze recall accuracy, build times, memory footprints, and query latency.
Read more