Building Production RAG with pgvector & Hybrid Search
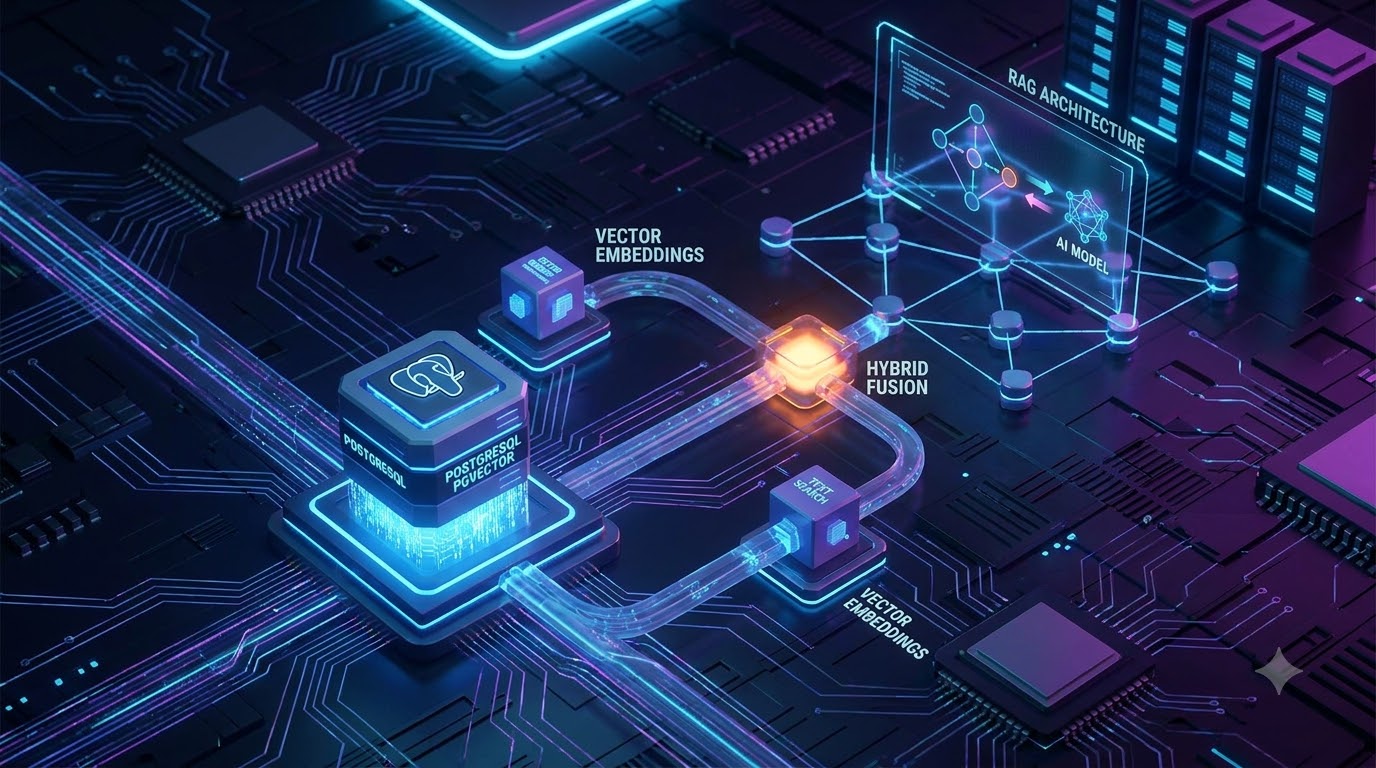
Table of Contents(13 sections)
When building a Retrieval-Augmented Generation (RAG) system, retrieval accuracy is everything. If the retrieved documents aren't relevant, your LLM's response won't be either. This is where pgvector hybrid search shines. By combining traditional full-text search with vector embeddings, you get the best of both worlds.
In this guide, we'll explore how to build a production-ready RAG architecture using PostgreSQL, the pgvector extension, Reciprocal Rank Fusion (RRF), and a complete Python client - including HNSW tuning, query plan analysis, and a production checklist.
If you are exploring other AI stack components, be sure to check out our overview of AI Tools.
SQL Query Optimizer & Index Advisor
Detect sargability anti-patterns & generate composite indexes
Analyze SQL queries for missing indexes, wildcard prefixes, and inefficient offset pagination. Generates optimized query rewrites and CREATE INDEX DDL for PostgreSQL and SQLite.
The RAG Architecture
Let's look at how a hybrid search RAG architecture operates under the hood. The system performs two parallel searches: a dense vector search for semantic meaning and a sparse keyword search (BM25) for exact matches. Then, it merges the results using Reciprocal Rank Fusion (RRF).
Dense vs. Sparse Search
Why do we need a hybrid approach? Let's break down the differences between semantic vector searches and traditional keyword matching.
While semantic search is powerful, it sometimes fails when a user searches for specific serial numbers, acronyms, or exact names. Combining it with PostgreSQL full-text search ensures you catch both exact terms and conceptual matches.
Choosing Your Embedding Dimension
Before setting up the schema, decide on your embedding model. The dimension you pick is permanent - changing it requires re-indexing all documents.
| Model | Dimensions | Notes |
|---|---|---|
OpenAI text-embedding-3-small | 1536 | Good balance of cost and quality |
OpenAI text-embedding-3-large | 3072 | Highest quality, 2× storage |
Cohere embed-english-v3.0 | 1024 | Strong multilingual option |
BAAI/bge-m3 (open source) | 1024 | Best open-source, self-hosted |
all-MiniLM-L6-v2 | 384 | Fast, low memory, good for on-device |
Larger dimensions improve recall on nuanced semantic queries but cost more in both storage and search latency. For most production RAG systems, 1024 or 1536 is the sweet spot.
Setting Up pgvector
Enable Extensions
First, enable pgvector in your database. On RDS or Supabase, this is available by default.
CREATE EXTENSION IF NOT EXISTS vector;
Create the Table
Create a table that stores your documents, their full-text search vectors (for BM25), and their embeddings.
CREATE TABLE documents (
    id          bigserial PRIMARY KEY,
    content     text      NOT NULL,
    metadata    jsonb     DEFAULT '{}',
    embedding   vector(1536),  -- match your model's dimension
    fts         tsvector  GENERATED ALWAYS AS
                  (to_tsvector('english', content)) STORED,
    created_at  timestamptz DEFAULT now()
);
Create the HNSW Index
HNSW provides faster query times and better recall than IVFFlat. Tune m (graph connectivity) and ef_construction (build-time search depth) to match your workload.
CREATE INDEX documents_embedding_hnsw_idx
    ON documents
    USING hnsw (embedding vector_cosine_ops)
    WITH (m = 16, ef_construction = 64);
m = 16: connections per node - higher improves recall but uses more memoryef_construction = 64: search depth at build time - higher improves index quality, slower to build
Create the Full-Text Index
Add a GIN index to accelerate BM25-style keyword queries.
CREATE INDEX documents_fts_gin_idx ON documents USING GIN (fts);
Set Query-Time HNSW Parameters
At query time, control the recall vs. latency tradeoff with hnsw.ef_search. Higher values improve recall at the cost of latency.
SET hnsw.ef_search = 100; -- default is 40; 100 is good for production
Set this per-session or in your connection pool configuration.
Implementing Hybrid Search with RRF
Reciprocal Rank Fusion combines the ranked results from both searches. A document that ranks #2 in vector search and #3 in keyword search gets a higher fused score than one that ranks #1 in only one of them.
WITH vector_search AS (
  SELECT id, content, metadata,
         RANK() OVER (ORDER BY embedding <=> $1) AS rank
  FROM documents
  ORDER BY embedding <=> $1
  LIMIT 50
),
keyword_search AS (
  SELECT id, content, metadata,
         RANK() OVER (
           ORDER BY ts_rank_cd(fts, plainto_tsquery('english', $2)) DESC
         ) AS rank
  FROM documents
  WHERE fts @@ plainto_tsquery('english', $2)
  ORDER BY ts_rank_cd(fts, plainto_tsquery('english', $2)) DESC
  LIMIT 50
)
SELECT
  COALESCE(v.id, k.id)               AS id,
  COALESCE(v.content, k.content)     AS content,
  COALESCE(v.metadata, k.metadata)   AS metadata,
  (
    COALESCE(1.0 / (60 + v.rank), 0.0) +
    COALESCE(1.0 / (60 + k.rank), 0.0)
  )                                   AS rrf_score
FROM vector_search v
FULL OUTER JOIN keyword_search k ON v.id = k.id
ORDER BY rrf_score DESC
LIMIT 10;
-- $1: embedding vector, $2: query text string
The constant 60 in the denominator is the RRF constant k - it reduces the weight of the top-ranked documents and prevents any single list from dominating. A value of 60 is the standard used in the original RRF paper.
Verifying Your Query Plan
Before shipping to production, run EXPLAIN ANALYZE to confirm the HNSW index is being used and check actual vs. estimated row counts:
EXPLAIN (ANALYZE, BUFFERS, FORMAT TEXT)
SELECT id, content, embedding <=> '[0.1, 0.2, ...]' AS dist
FROM documents
ORDER BY embedding <=> '[0.1, 0.2, ...]'
LIMIT 10;
Look for Index Scan using documents_embedding_hnsw_idx in the output. If you see a sequential scan instead, your ef_search may be too high or statistics need updating (ANALYZE documents;).
Python Client with asyncpg
Here's a production-grade Python implementation using asyncpg and OpenAI embeddings:
import asyncpg
import openai
from typing import Any

async def embed(text: str) -> list[float]:
    resp = await openai.AsyncOpenAI().embeddings.create(
        model="text-embedding-3-small",
        input=text,
    )
    return resp.data[0].embedding

async def hybrid_search(
    pool: asyncpg.Pool,
    query: str,
    limit: int = 10,
) -> list[dict[str, Any]]:
    embedding = await embed(query)
    # asyncpg expects vectors as lists of floats
    vector_str = "[" + ",".join(str(x) for x in embedding) + "]"

    rows = await pool.fetch(
        """
        WITH vector_search AS (
          SELECT id, content, metadata,
                 RANK() OVER (ORDER BY embedding <=> $1::vector) AS rank
          FROM documents ORDER BY embedding <=> $1::vector LIMIT 50
        ),
        keyword_search AS (
          SELECT id, content, metadata,
                 RANK() OVER (
                   ORDER BY ts_rank_cd(fts, plainto_tsquery('english', $2)) DESC
                 ) AS rank
          FROM documents
          WHERE fts @@ plainto_tsquery('english', $2)
          LIMIT 50
        )
        SELECT
          COALESCE(v.id, k.id)             AS id,
          COALESCE(v.content, k.content)   AS content,
          COALESCE(v.metadata, k.metadata) AS metadata,
          (COALESCE(1.0/(60+v.rank),0) + COALESCE(1.0/(60+k.rank),0)) AS score
        FROM vector_search v
        FULL OUTER JOIN keyword_search k ON v.id = k.id
        ORDER BY score DESC LIMIT $3
        """,
        vector_str,
        query,
        limit,
    )
    return [dict(r) for r in rows]
Chunking Strategy
How you split your documents before embedding is as important as the index configuration. Poor chunking causes two failure modes:
- Chunks too small: The embedding captures only part of a concept, semantic search misses context.
- Chunks too large: A single chunk dilutes relevance - one relevant sentence buried in 2,000 tokens.
| Strategy | Chunk Size | Overlap | Best For |
|---|---|---|---|
| Fixed token | 512 tokens | 50 tokens | General purpose, simple to implement |
| Sentence boundary | 3-5 sentences | 1 sentence | Conversational docs, QA systems |
| Paragraph boundary | 1 paragraph | - | Blog posts, articles |
| Semantic chunking | Variable | - | Long technical docs with logical sections |
For most RAG applications, 512 tokens with 50-token overlap is a solid starting point. Overlap ensures a concept split across a chunk boundary still appears in at least one chunk's context window.
Optional: Re-Ranking with a Cross-Encoder
RRF is a good fuser, but it doesn't understand the query-document relationship - it only combines rankings. For high-stakes RAG (medical, legal, financial), add a cross-encoder re-ranking step after retrieval:
from sentence_transformers import CrossEncoder

reranker = CrossEncoder('cross-encoder/ms-marco-MiniLM-L-6-v2')

def rerank(query: str, docs: list[dict]) -> list[dict]:
    pairs = [(query, d['content']) for d in docs]
    scores = reranker.predict(pairs)
    ranked = sorted(zip(docs, scores), key=lambda x: x[1], reverse=True)
    return [d for d, _ in ranked]
Cross-encoders are slower than bi-encoders (they process each query-document pair jointly), so only re-rank the top 20-50 results from hybrid search, then pass the top 5-10 to the LLM.
Test Your Knowledge
FAQ
Production Checklist
Before going live with your hybrid RAG pipeline:
- ☑ Set
hnsw.ef_search = 100(or higher) on your connection pool - the default 40 sacrifices too much recall - ☑ Verify query plan uses the HNSW index with
EXPLAIN ANALYZE - ☑ Run
VACUUM ANALYZE documentsafter bulk inserts to update statistics - ☑ Store
metadata(source URL, section, date) injsonbfor post-retrieval filtering - ☑ Add
WHERE metadata @> '{"source": "docs"}'::jsonbto filter by source before ranking - ☑ Monitor embedding API latency separately from DB query latency in your observability stack
- ☑ Set
statement_timeouton hybrid search queries to avoid slow queries blocking your LLM pipeline - ☑ Use
asyncpgconnection pools (min 2, max 20) - avoid creating a new connection per request
By combining these methods into a cohesive PostgreSQL hybrid search RAG pipeline, you dramatically improve the precision and reliability of your AI application.
You Might Also Like
Free In-Browser Developer Tools
Clean AI CLI logs, build cron expressions, decode JWTs, and calculate chmod permissions offline.
Related Articles
pgvector in Production: High-Scale Vector Search & Hybrid RRF in PostgreSQL
Production guide to pgvector in PostgreSQL: HNSW vs IVFFlat indexing, parameter tuning, hybrid full-text search with RRF, and metadata filtering.
Read more
pgvector vs Qdrant at Scale: Memory Overhead, HNSW Recall & Tail Latencies (2026)
Comprehensive guide covering pgvector vs qdrant at scale: memory overhead, hnsw recall & tail latencies (2026) with production-grade architecture and code examples.
Read more
Vector Search at Scale: HNSW vs IVFFlat Indexing in pgvector and SQLite-vec
Compare HNSW and IVFFlat vector indexing algorithms in pgvector and sqlite-vec. Analyze recall accuracy, build times, memory footprints, and query latency.
Read more