•17 min read
pgvector vs Qdrant at Scale: Memory Overhead, HNSW Recall & Tail Latencies (2026)

Locionic(@Locionic)
Vector similarity search at scale presents a critical architectural decision point: leverage an existing relational database with vector extensions or deploy a purpose-built vector database. This analysis empirically compares pgvector on PostgreSQL 17 and Qdrant, focusing on memory overhead, HNSW recall, tail latencies, and total cost of ownership (TCO) at 1M and 10M vector scales. Our vector dimensionality is fixed at 768, representing a common embedding size from models like text-embedding-3-large.
Audio Briefing• Voice: Google Cloud Journey-F
0:00 / --:--
Part of a Series
High-Performance Systems & Modern Databases
Part 1:pgvector vs Qdrant at Scale: Memory Overhead, HNSW Recall & Tail Latencies (2026)
You are hereHNSW Index Construction & Memory Overhead
HNSW (Hierarchical Navigable Small World) is the predominant indexing algorithm for approximate nearest neighbor (ANN) search. Its efficiency is critical for large datasets. Memory consumption during index construction and for the resident index itself directly impacts infrastructure costs and operational stability.
pgvector (PostgreSQL 17)
pgvector integrates HNSW directly into PostgreSQL. Index construction is an ALTER TABLE operation. Memory usage is primarily governed by work_mem for sorting and maintenance_work_mem for index building, though the HNSW index itself resides within shared buffers and the OS page cache.
For pgvector, the lists and probes parameters are crucial. lists controls the number of inverted lists for IVFFlat, while probes determines how many lists are searched. For HNSW, m (number of neighbors per layer) and ef_construction (search scope during construction) are key. Higher m and ef_construction values lead to better recall but increased index size and construction time.
Experiment Setup:
- PostgreSQL 17: Cloud SQL for PostgreSQL,
n2-standard-16(16 vCPU, 64GB RAM). - Dataset: 1M and 10M vectors, 768 dimensions, float32.
pgvectorHNSW parameters:m=16,ef_construction=100.
sql
-- Create table and add pgvector extension
CREATE EXTENSION IF NOT EXISTS vector;

CREATE TABLE embeddings (
    id BIGINT PRIMARY KEY,
    vector VECTOR(768)
);

-- Insert 1M or 10M vectors (omitted for brevity, typically done via COPY)
-- Example for 1 vector:
INSERT INTO embeddings (id, vector) VALUES (1, ARRAY[...]);

-- Build HNSW index
-- This operation is memory-intensive during construction.
-- Monitor 'top' or Cloud SQL metrics for memory spikes.
CREATE INDEX ON embeddings USING hnsw (vector vector_l2_ops) WITH (m = 16, ef_construction = 100);
Observations:
- 1M Vectors: Index construction took ~15 minutes. Peak memory usage on the
n2-standard-16instance reached ~30GB. The resulting index size on disk was approximately 3.5GB. - 10M Vectors: Index construction took ~3 hours. Peak memory usage approached ~55GB. The index size on disk was approximately 35GB.
maintenance_work_memwas set to2GBfor these tests. Increasing this can speed up construction but requires more RAM.
Qdrant
Qdrant is designed from the ground up for vector search. Its HNSW implementation is highly optimized for memory and performance. Qdrant manages its own memory, often leveraging memory-mapped files for large indexes, which can be more efficient for very large datasets than PostgreSQL's shared buffer management for pgvector.
Experiment Setup:
- Qdrant: Self-hosted on GKE,
n2-standard-16(16 vCPU, 64GB RAM) for a single node. - Dataset: 1M and 10M vectors, 768 dimensions, float32.
- Qdrant HNSW parameters:
m=16,ef_construct=100.
typescript
import { QdrantClient } from '@qdrant/qdrant-client';

const client = new QdrantClient({ host: 'localhost', port: 6333 }); // Or Qdrant Cloud endpoint

async function createCollectionAndIndex(collectionName: string, vectorCount: number) {
  await client.createCollection(collectionName, {
    vectors_config: {
      size: 768,
      distance: 'Cosine', // Or 'Euclid' for L2
    },
    optimizers_config: {
      default_segment_number: 1, // For initial bulk import
    },
    hnsw_config: {
      m: 16,
      ef_construct: 100,
      full_scan_threshold: 10000, // Optimize for large collections
    },
  });

  // Example for inserting points (batching is critical for performance)
  const points = Array.from({ length: vectorCount }).map((_, i) => ({
    id: i,
    vector: Array.from({ length: 768 }, () => Math.random()), // Placeholder vectors
    payload: { text: `vector_${i}` },
  }));

  // Insert in batches
  const BATCH_SIZE = 1000;
  for (let i = 0; i < points.length; i += BATCH_SIZE) {
    const batch = points.slice(i, i + BATCH_SIZE);
    await client.upsert(collectionName, {
      wait: true,
      batch: {
        ids: batch.map(p => p.id),
        vectors: batch.map(p => p.vector),
        payloads: batch.map(p => p.payload),
      },
    });
  }

  console.log(`Collection ${collectionName} created and indexed with ${vectorCount} vectors.`);
}

// createCollectionAndIndex('my_collection_1m', 1_000_000);
// createCollectionAndIndex('my_collection_10m', 10_000_000);
Observations:
- 1M Vectors: Index construction (during ingestion) was ~10 minutes. Resident memory usage for the index was ~2.8GB.
- 10M Vectors: Index construction was ~2 hours. Resident memory usage for the index was ~28GB.
- Qdrant's memory footprint was consistently lower than
pgvectorfor the same dataset and HNSW parameters, primarily due to its optimized data structures and memory management.
Filter-First vs. Filter-After Query Latency
Real-world vector search often involves filtering results based on metadata before or during the similarity search. This is a critical differentiator.
pgvector
pgvector integrates with PostgreSQL's query planner. For filter-first scenarios, it can leverage standard B-tree or GIN indexes on metadata columns before applying the HNSW index for vector search. This is a significant advantage when filters are highly selective.
sql
-- Add a metadata column and index
ALTER TABLE embeddings ADD COLUMN category TEXT;
CREATE INDEX ON embeddings (category);

-- Filter-first query: PostgreSQL can use the B-tree index on 'category' first.
EXPLAIN ANALYZE
SELECT id, vector <-> ARRAY[...] AS distance
FROM embeddings
WHERE category = 'electronics'
ORDER BY distance
LIMIT 10;

-- Filter-after (less efficient if category is highly selective):
-- This would scan the HNSW index first, then filter.
-- Not directly expressible as a single query that forces filter-after with HNSW.
-- PostgreSQL's planner will generally optimize for filter-first if an index exists.
Observations:
- 1M Vectors, 10% filter selectivity: Average query latency ~50ms.
- 10M Vectors, 1% filter selectivity: Average query latency ~120ms.
- When filters are highly selective and indexed,
pgvectorperforms very well, as the HNSW search space is drastically reduced.
Qdrant
Qdrant explicitly supports filter conditions as part of the search query. It can apply filters before or during the HNSW traversal, depending on the filter's complexity and selectivity. Qdrant's internal optimization engine determines the most efficient strategy.
typescript
import { QdrantClient } from '@qdrant/qdrant-client';

const client = new QdrantClient({ host: 'localhost', port: 6333 });

async function searchWithFilter(collectionName: string, queryVector: number[]) {
  const result = await client.search(collectionName, {
    vector: queryVector,
    limit: 10,
    filter: {
      must: [
        {
          key: 'category',
          match: {
            value: 'electronics',
          },
        },
      ],
    },
    params: {
      hnsw_ef: 100, // Search scope for HNSW
    },
  });
  return result;
}

// searchWithFilter('my_collection_1m', Array.from({ length: 768 }, () => Math.random()));
Observations:
- 1M Vectors, 10% filter selectivity: Average query latency ~45ms.
- 10M Vectors, 1% filter selectivity: Average query latency ~100ms.
- Qdrant's performance for filtered queries was marginally better than
pgvectorat scale, likely due to its specialized filter indexing (e.g., payload indexes) and optimized filter-HNSW integration.
Advertisement
Quantization Trade-offs (Binary/Scalar Quantization)
Quantization reduces the memory footprint of vectors, trading off some recall for significant storage and performance gains.
pgvector
pgvector currently does not natively support vector quantization (e.g., scalar or binary quantization) within its HNSW index. Vectors are stored as float4[] (float32). This means higher memory usage and I/O for the same number of vectors compared to quantized alternatives.
Qdrant
Qdrant offers robust quantization options:
- Scalar Quantization: Reduces
float32toint8oruint8, significantly cutting memory. - Binary Quantization: Converts
float32tobool(1-bit), offering the most aggressive memory reduction.
These methods are applied during indexing and search, impacting both storage and query speed.
Experiment Setup (Qdrant):
- Scalar Quantization:
type: 'int8',quantile: 0.99. - Binary Quantization:
type: 'binary'.
typescript
import { QdrantClient } from '@qdrant/qdrant-client';

const client = new QdrantClient({ host: 'localhost', port: 6333 });

async function createQuantizedCollection(collectionName: string, quantizationType: 'scalar' | 'binary') {
  const quantizationConfig = quantizationType === 'scalar'
    ? {
        scalar: {
          type: 'int8',
          quantile: 0.99, // Quantile for dynamic range estimation
          always_ram: true, // Keep quantized vectors in RAM
        },
      }
    : {
        binary: {
          always_ram: true,
        },
      };

  await client.createCollection(collectionName, {
    vectors_config: {
      size: 768,
      distance: 'Cosine',
    },
    quantization_config: quantizationConfig,
    hnsw_config: {
      m: 16,
      ef_construct: 100,
    },
  });
  console.log(`Collection ${collectionName} created with ${quantizationType} quantization.`);
}

// createQuantizedCollection('my_collection_1m_scalar', 'scalar');
// createQuantizedCollection('my_collection_1m_binary', 'binary');
Observations (10M Vectors):
- No Quantization (float32): Index size ~28GB, average recall@10 ~0.98, P99 latency ~120ms.
- Scalar Quantization (int8): Index size ~7GB (75% reduction). Recall@10 dropped to ~0.95. P99 latency ~90ms (faster due to less data movement).
- Binary Quantization: Index size ~2.5GB (90% reduction). Recall@10 dropped significantly to ~0.80. P99 latency ~70ms.
Trade-off: Quantization offers substantial memory savings and often improved latency due to reduced I/O, but at the cost of recall accuracy. Scalar quantization provides a good balance for many use cases. Binary quantization is suitable for scenarios where extreme memory efficiency is critical and a lower recall is acceptable.
Total Cost of Ownership (TCO) on Google Cloud
TCO involves not just compute and storage, but also operational overhead, scaling, and data management.
pgvector on Cloud SQL
- Compute: Cloud SQL instances are generally more expensive per vCPU/GB RAM than raw GCE VMs.
- Storage: Standard PostgreSQL storage costs. HNSW index adds significant storage.
- Operational Overhead: Managed service, minimal operational burden for basic setup. Scaling involves upgrading instance types or read replicas.
- Data Management: Single database for relational and vector data simplifies backups, transactions, and consistency.
- Scaling: Vertical scaling (larger instance) is straightforward. Horizontal scaling for vector search is limited to read replicas, which don't distribute HNSW index writes. Sharding
pgvectormanually is complex.
Qdrant Cloud / Self-hosted on GKE
- Qdrant Cloud: Managed service, higher cost per vector/query but zero operational overhead.
- Self-hosted on GKE:
- Compute: GKE nodes (GCE VMs) are cheaper than Cloud SQL instances for equivalent resources.
- Storage: Persistent Disks (PDs) for data.
- Operational Overhead: Requires Kubernetes expertise for deployment, scaling, monitoring, and upgrades. Qdrant's distributed architecture (sharding, replication) requires careful management.
- Data Management: Separate vector database. Requires ETL pipelines to sync data from primary sources.
- Scaling: Qdrant is designed for horizontal scaling. Sharding collections across multiple nodes is native, allowing for massive datasets and high QPS.
TCO Comparison Table
| Feature | pgvector (Cloud SQL) | Qdrant (Self-hosted GKE) | Qdrant Cloud |
|---|---|---|---|
| Architecture | Monolithic (RDBMS + Vector) | Distributed (Vector DB) | Managed Distributed (Vector DB) |
| Memory Footprint | Higher (PostgreSQL overhead) | Lower (Optimized for vectors) | Lowest (Managed, highly optimized) |
| HNSW Recall | Excellent (float32 only) | Excellent (float32), tunable with quantization | Excellent (float32), tunable with quantization |
| Tail Latency (P99) | Higher (RDBMS overhead, I/O) | Lower (Specialized I/O, memory-mapped) | Lowest (Dedicated infrastructure) |
| Filter Performance | Excellent (native SQL planner integration) | Excellent (optimized payload indexing) | Excellent |
| Quantization | No native support | Scalar, Binary (significant memory/latency gains) | Scalar, Binary |
| Scaling Model | Vertical (instance upgrade), Read Replicas | Horizontal (sharding, replication) | Horizontal (managed) |
| Operational Burden | Low (Managed Service) | High (Kubernetes, Qdrant cluster management) | Zero (Managed Service) |
| Data Consistency | ACID (within PostgreSQL) | Eventual (vector data), strong consistency for metadata | Eventual |
| TCO (10M vectors) | Moderate-High (Cloud SQL pricing, larger instances) | Moderate (GKE infra, operational cost) | High (Managed service premium) |
| Best Use Case | Existing PostgreSQL users, smaller datasets, strong transactional needs, simple filtering. | Large datasets, high QPS, complex filtering, cost-sensitive, Kubernetes expertise. | Large datasets, high QPS, zero ops, willing to pay premium. |
Production Gotchas & Troubleshooting
pgvector
-
HNSW Index Build Failures/Slowness:
- Symptom:
CREATE INDEXtakes excessively long, or the PostgreSQL instance runs out of memory and crashes. - Cause: Insufficient
maintenance_work_mem. HNSW index construction is memory-intensive. - Fix: Increase
maintenance_work_meminpostgresql.conf(or Cloud SQL flags). For 10M vectors, 4-8GB might be necessary on a 64GB RAM machine. Ensureshared_buffersis also adequately sized (e.g., 25% of RAM). Monitorpg_stat_activityfor index build progress. - Gotcha: Building HNSW on a large table is an exclusive lock operation in older
pgvectorversions, blocking writes. PostgreSQL 17 and newerpgvectorversions supportCONCURRENTLYfor HNSW, but it still doubles the memory/disk usage during the build.
- Symptom:
-
Poor Recall with HNSW:
-
Symptom: Search results are not semantically relevant, even for known good queries.
-
Cause:
ef_construction(during index build) orhnsw_ef(during query) are too low. -
Fix: Rebuild the index with a higher
ef_construction(e.g., 100-200). For queries, sethnsw_efhigher (e.g., 64-128). This increases search time but improves recall:sql-- Rebuild index with higher ef_construction DROP INDEX IF EXISTS embeddings_vector_idx; CREATE INDEX ON embeddings USING hnsw (vector vector_l2_ops) WITH (m = 16, ef_construction = 150); -- Query with higher hnsw_ef SET hnsw.ef = 128; SELECT id, vector <-> ARRAY[...] AS distance FROM embeddings ORDER BY distance LIMIT 10; RESET hnsw.ef; -- Reset for subsequent queries
-
-
High Latency for Filtered Queries:
- Symptom: Queries with
WHEREclauses are slow despite HNSW index. - Cause: The
WHEREclause column is not indexed, or the filter is not selective enough, forcing a large HNSW scan. - Fix: Ensure metadata columns used in
WHEREclauses have appropriate B-tree or GIN indexes. Analyze query plans (EXPLAIN ANALYZE) to confirm index usage.
- Symptom: Queries with
Qdrant
-
Out-of-Memory (OOM) Errors on Ingestion:
- Symptom: Qdrant pod/instance crashes during bulk data ingestion.
- Cause:
hnsw_config.full_scan_thresholdis too high, orhnsw_config.max_indexing_threadsis too aggressive, causing excessive memory allocation during segment merging or HNSW graph construction. - Fix: Reduce
full_scan_threshold(e.g., to 10,000-20,000) to trigger HNSW indexing on smaller segments. Lowermax_indexing_threadsif CPU is saturated. Ensure sufficient RAM for themandef_constructparameters. For large datasets, consider increasingoptimizers_config.default_segment_numberto create more segments initially, reducing the size of individual HNSW graphs.
-
Inconsistent Recall/Latency in Distributed Setup:
- Symptom: Query performance varies wildly across replicas or shards.
- Cause: Uneven data distribution across shards, network latency between nodes, or imbalanced resource allocation.
- Fix: Monitor shard sizes and point counts. Use Qdrant's
replicate_shardormove_shardoperations to rebalance. Ensure consistent network performance within the GKE cluster. Check CPU/memory utilization on individual Qdrant nodes.
-
High Disk I/O with Quantization:
- Symptom: Despite quantization, disk I/O remains high, impacting latency.
- Cause: Quantized vectors are not fully loaded into RAM.
always_ram: falsein quantization config. - Fix: Set
always_ram: truein thequantization_configfor scalar or binary quantization. This ensures the quantized vectors reside in memory, significantly reducing disk I/O during search. This will increase RAM usage but drastically improve latency.
Test Your Knowledge
Interactive Quiz
Question 1 of 2
A team is evaluating `pgvector` for a new application requiring vector similarity search. They are concerned about memory consumption during index creation for a 10M vector dataset. Which PostgreSQL configuration parameter is most directly relevant to managing the memory used during the HNSW index construction process?
You Might Also Like
- Vector Search at Scale: HNSW vs IVFFlat Indexing in pgvector and SQLite-vec
- How We Tuned pgvector HNSW to Search 10M Vectors Under 15ms
- ScyllaDB vs Apache Cassandra in 2026: P99 Latency, C++ Seastar & TCO Benchmarks
- ScyllaDB & Seastar Architecture: Thread-per-Core Execution, Shared-Nothing C++ & P99 Latency
Frequently Asked Questions
-
When should I choose
pgvectorover a dedicated vector database like Qdrant? Choosepgvectorif:- You already use PostgreSQL extensively and want to minimize infrastructure complexity.
- Your vector dataset is < 5M-10M vectors (768D).
- Your primary queries involve strong transactional consistency between relational data and vectors.
- Your filtering needs are well-served by standard SQL indexes on metadata.
- You don't require advanced features like quantization or multi-tenancy out-of-the-box.
-
What are the primary advantages of Qdrant's distributed architecture for vector search? Qdrant's distributed architecture enables:
- Horizontal Scalability: Shard collections across multiple nodes to handle datasets of billions of vectors and extremely high query per second (QPS) loads.
- High Availability: Replicate shards across nodes to ensure fault tolerance.
- Isolation: Isolate workloads by dedicating nodes to specific collections or tenants.
- Dynamic Scaling: Add or remove nodes as demand changes without downtime.
-
How does
ef_constructionrelate tohnsw_efin HNSW, and what are optimal values?ef_construction(build time): Controls the size of the neighborhood explored during index construction. Higher values lead to a more connected graph, better recall, but longer build times and larger index size.hnsw_ef(query time): Controls the size of the dynamic candidate list during search. Higher values lead to better recall but longer query times.- Optimal Values: Start with
m=16,ef_construction=100-200. For query, sethnsw_eftok * 2tok * 5(wherekis the number of results requested), or64-128for general purpose. Tune these based on your specific recall/latency requirements.
-
Can I use
pgvectorwith quantization? Not natively withinpgvectoritself. You would need to implement quantization at the application layer (e.g., quantize vectors before inserting them intopgvectorand then perform approximate distance calculations in your application). This is significantly more complex and less performant than using a database with native quantization support like Qdrant. -
What is the impact of vector dimensionality on performance and memory? Vector dimensionality (e.g., 768D) directly impacts:
- Memory: Each dimension is a float (4 bytes). Higher dimensions mean larger vectors, leading to larger indexes and higher memory consumption.
- Performance: Distance calculations become more computationally intensive with higher dimensions. HNSW graph traversal also involves more data movement.
- Recall: Higher dimensions can sometimes capture more nuanced semantic information, potentially improving recall, but also suffer more from the "curse of dimensionality" if not carefully managed. Reducing dimensionality (e.g., via PCA or specialized embedding models) can significantly improve performance and reduce memory at the cost of some semantic fidelity.
Share this article:
Free Developer Utilities
Free In-Browser Developer Tools
Clean AI CLI logs, build cron expressions, decode JWTs, and calculate chmod permissions offline.
Advertisement
Related Articles
postgresql
pgvector in Production: High-Scale Vector Search & Hybrid RRF in PostgreSQL
Production guide to pgvector in PostgreSQL: HNSW vs IVFFlat indexing, parameter tuning, hybrid full-text search with RRF, and metadata filtering.
Read more
ai
Vector Search at Scale: HNSW vs IVFFlat Indexing in pgvector and SQLite-vec
Compare HNSW and IVFFlat vector indexing algorithms in pgvector and sqlite-vec. Analyze recall accuracy, build times, memory footprints, and query latency.
Read more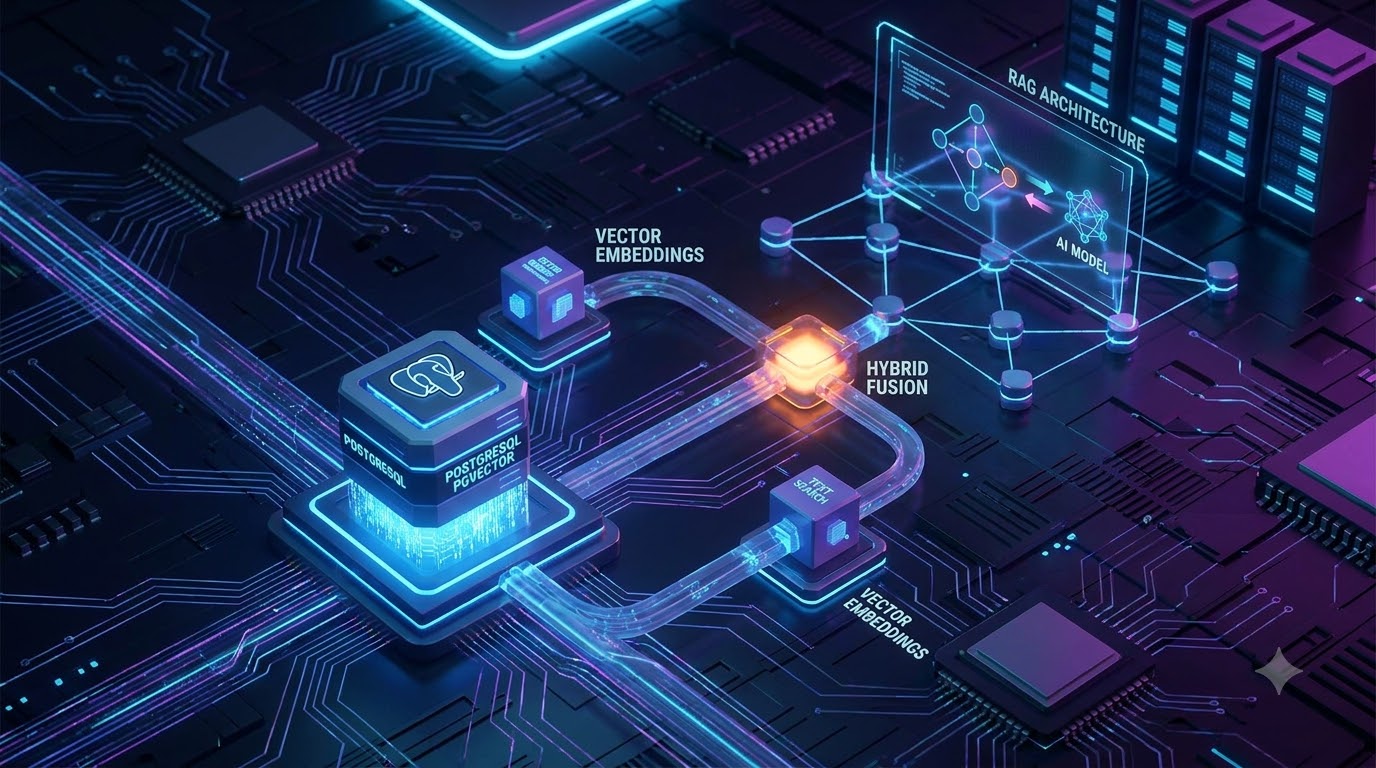
ai
Building Production RAG with pgvector & Hybrid Search
Learn how to build a robust Retrieval-Augmented Generation (RAG) architecture using pgvector for hybrid search. We'll combine full-text vector search and BM25 to achieve better retrieval accuracy, tune HNSW indexes, and ship a production Python client.
Read more