Fine-Tuning DeepSeek R1 with Unsloth & LoRA: Memory-Efficient Reasoning Models
Comprehensive guide covering fine-tuning deepseek r1 with unsloth & lora: memory-efficient reasoning models with production-grade architecture and code examples.
Stories, tutorials, and deep dives spanning across diverse worlds.

Comprehensive guide covering fine-tuning deepseek r1 with unsloth & lora: memory-efficient reasoning models with production-grade architecture and code examples.

UnslothとLoRAでDeepSeek R1をファインチューニングし、本番環境レベルのアーキテクチャとコード例を用いてメモリ効率の良い推論モデルを構築するための包括的なガイドです。

Hướng dẫn toàn diện về tinh chỉnh DeepSeek R1 với Unsloth & LoRA: các mô hình suy luận tiết kiệm bộ nhớ với kiến trúc cấp độ sản xuất và ví dụ mã.

Comprehensive guide covering deepseek v3 architecture deep dive: multi-head latent attention (mla), deepseekmoe & fp8 mixed precision with production-grade architecture and code examples.
DeepSeek V3のアーキテクチャを深く掘り下げ、Multi-Head Latent Attention (MLA)、DeepSeekMoE、FP8混合精度、そして本番環境レベルのアーキテクチャとコード例を網羅した包括的なガイドです。

Hướng dẫn toàn diện về kiến trúc DeepSeek V3 chuyên sâu: Multi-Head Latent Attention (MLA), DeepSeekMoE & FP8 Mixed Precision với kiến trúc cấp độ sản xuất và ví dụ code.

An architectural benchmark of Pinecone, Qdrant, Milvus, and pgvector for production RAG pipelines: HNSW vs IVFFlat indexing, single-stage filtered search, p95 latency, and memory footprint.

本番RAGパイプライン向けにPinecone、Qdrant、Milvus、pgvectorのアーキテクチャを、HNSW vs IVFFlatインデックス、単段フィルタリング検索、p95レイテンシ、メモリフットプリントでベンチマークします。

Đánh giá kiến trúc của Pinecone, Qdrant, Milvus và pgvector cho các pipeline RAG sản xuất: lập chỉ mục HNSW vs IVFFlat, tìm kiếm được lọc một giai đoạn, độ trễ p95 và mức sử dụng bộ nhớ.

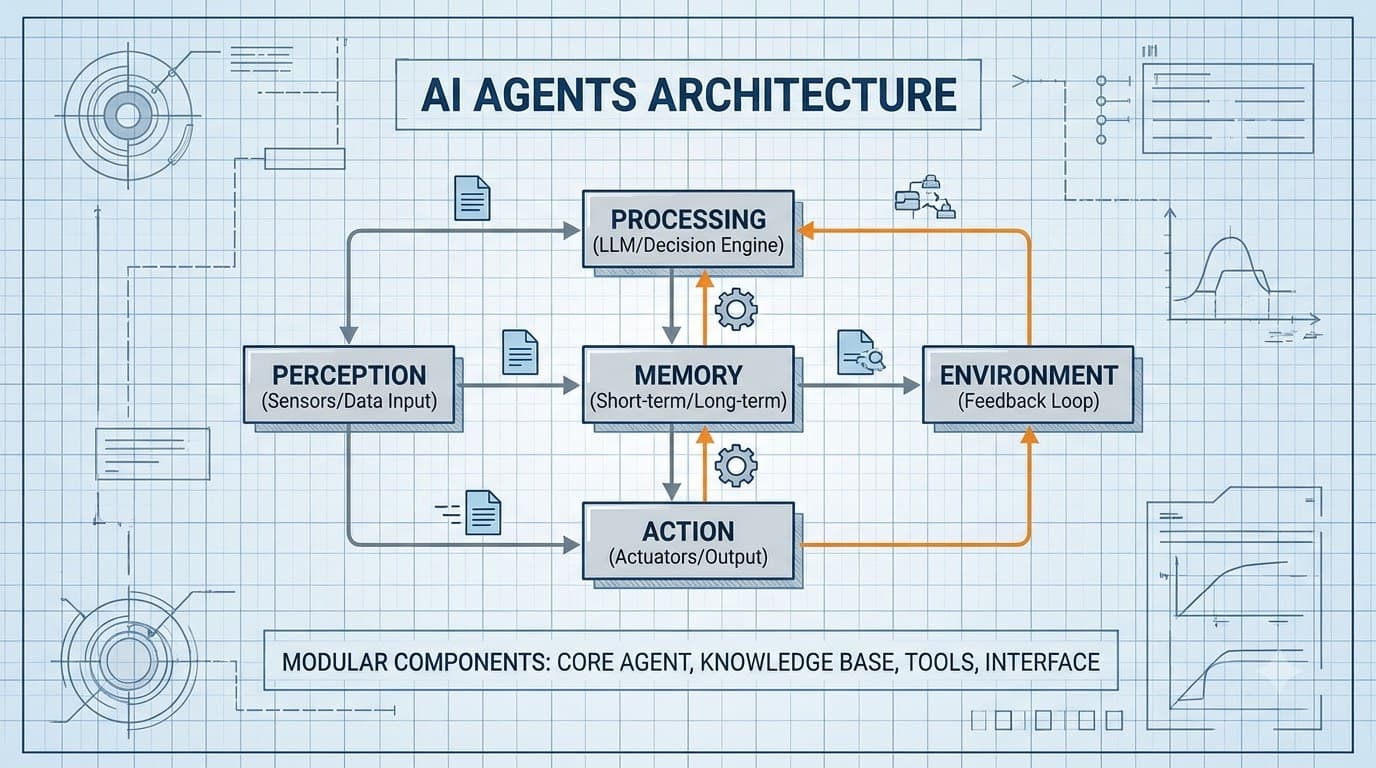
A working guide to building AI agent systems in 2026: ReAct loops, vector memory, tool calling patterns, multi-agent coordination, and how to test agents that fail gracefully.
Showing 1-10 of 26 posts