Fine-Tuning DeepSeek R1 with Unsloth & LoRA: Memory-Efficient Reasoning Models
Comprehensive guide covering Fine-Tuning DeepSeek R1 with Unsloth & LoRA: Memory-Efficient Reasoning Models with production-grade architecture and code examples.
Stories, tutorials, and deep dives spanning across diverse worlds.

Comprehensive guide covering Fine-Tuning DeepSeek R1 with Unsloth & LoRA: Memory-Efficient Reasoning Models with production-grade architecture and code examples.

Comprehensive guide covering DeepSeek V3 Architecture Deep Dive: Multi-Head Latent Attention (MLA), DeepSeekMoE & FP8 Mixed Precision with production-grade architecture and code examples.
An architectural benchmark of Pinecone, Qdrant, Milvus, and pgvector for production RAG pipelines: HNSW vs IVFFlat indexing, single-stage filtered search, p95 latency, and memory footprint.

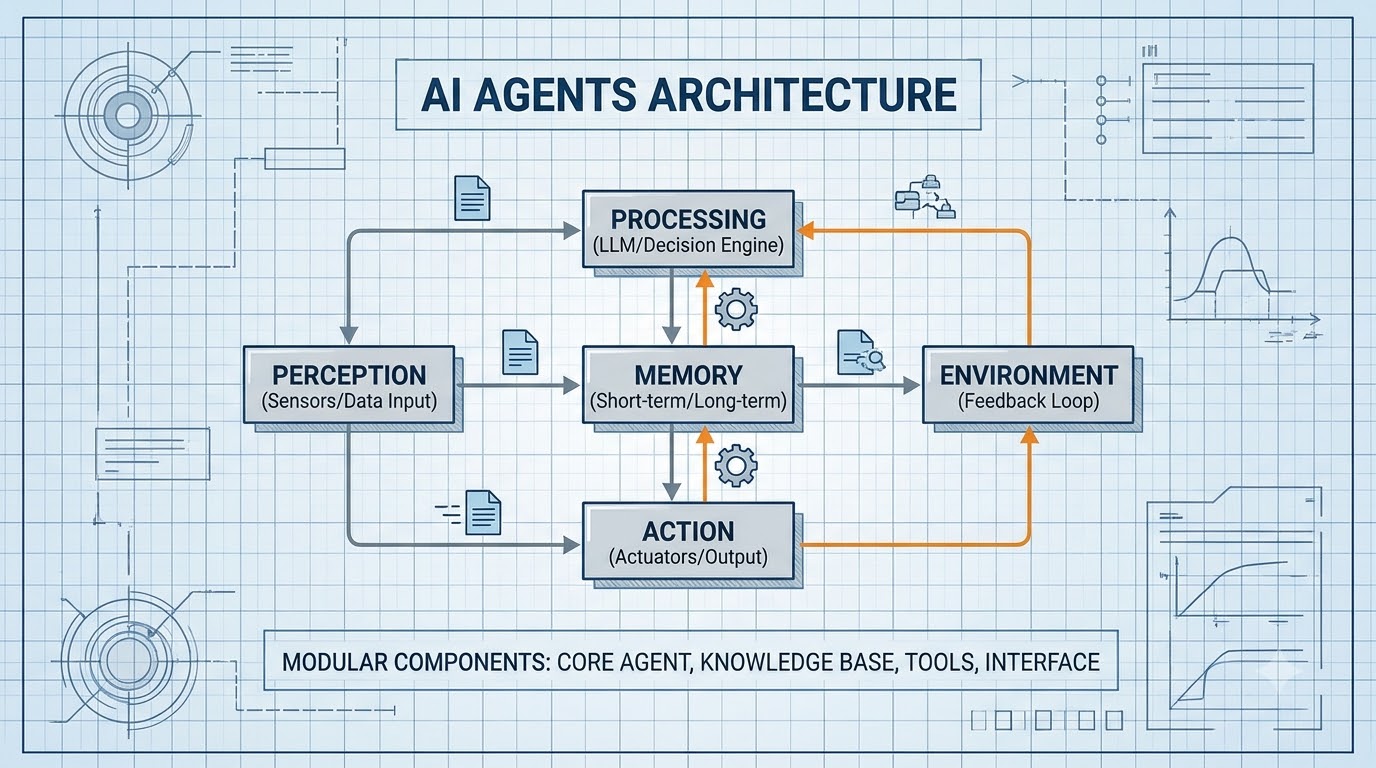
A working guide to building AI agent systems in 2026: ReAct loops, vector memory, tool calling patterns, multi-agent coordination, and how to test agents that fail gracefully.

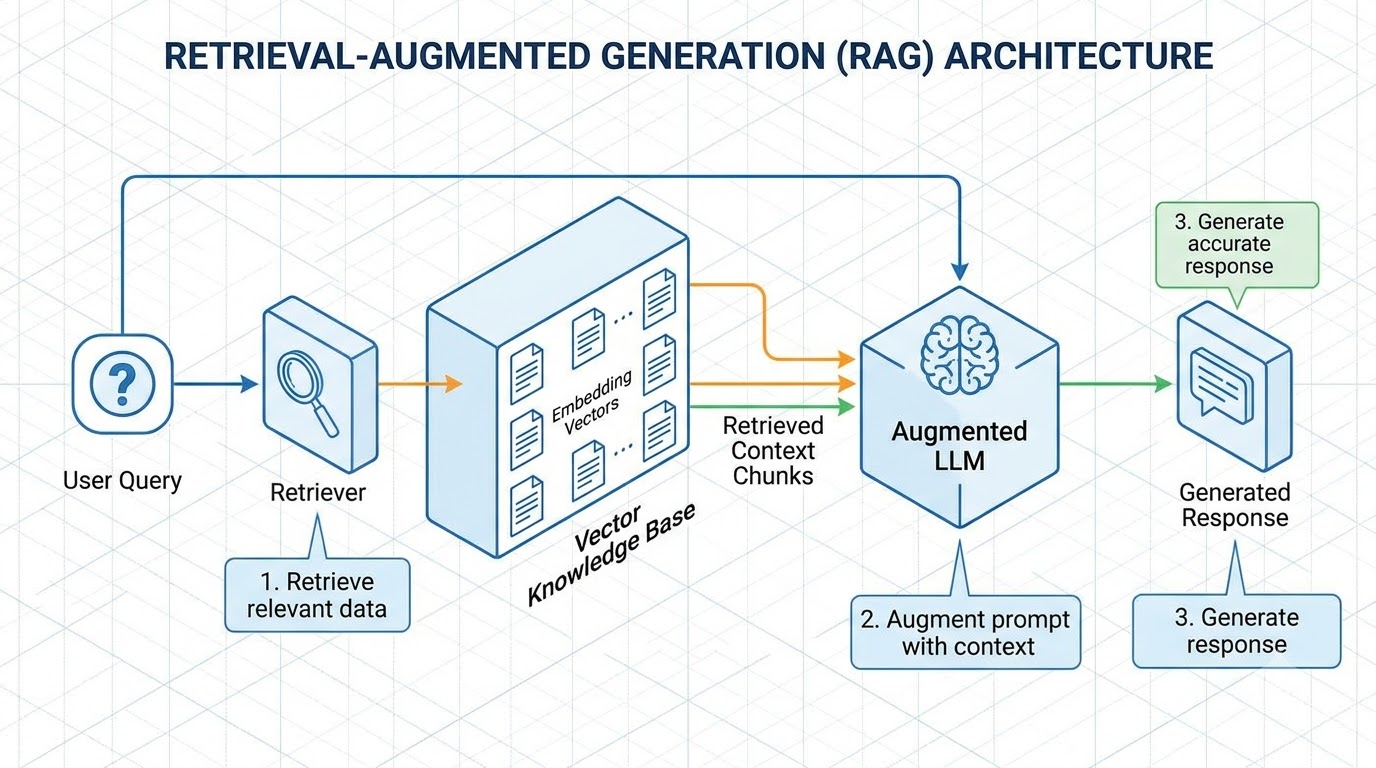
A deep dive into Retrieval-Augmented Generation (RAG): chunking strategies, vector embeddings, hybrid dense-sparse search, and reranking pipelines.

Stop using accuracy on imbalanced data: master Precision-Recall tradeoffs, F-beta scores, ROC-AUC vs PR-AUC, probability calibration (Brier score & Platt scaling), and threshold tuning.

Autonomous vehicles are moving AI inference out of the cloud and onto the car. Here's why latency, privacy, and safety leave no other option, plus the regulatory and societal questions that come with it.

What I've learned building fraud detection systems with AI after years of rules-based approaches: where ML actually helps, where it doesn't, and what deploying a model in production taught me.

I burned too many weekends on the wrong Python libraries so you don't have to. Here's what I actually use to ship things that stay working.