•6 min read
Python Concurrency in 2026: AsyncIO vs Threads vs Processes

The Multi-Threaded CPU Trap
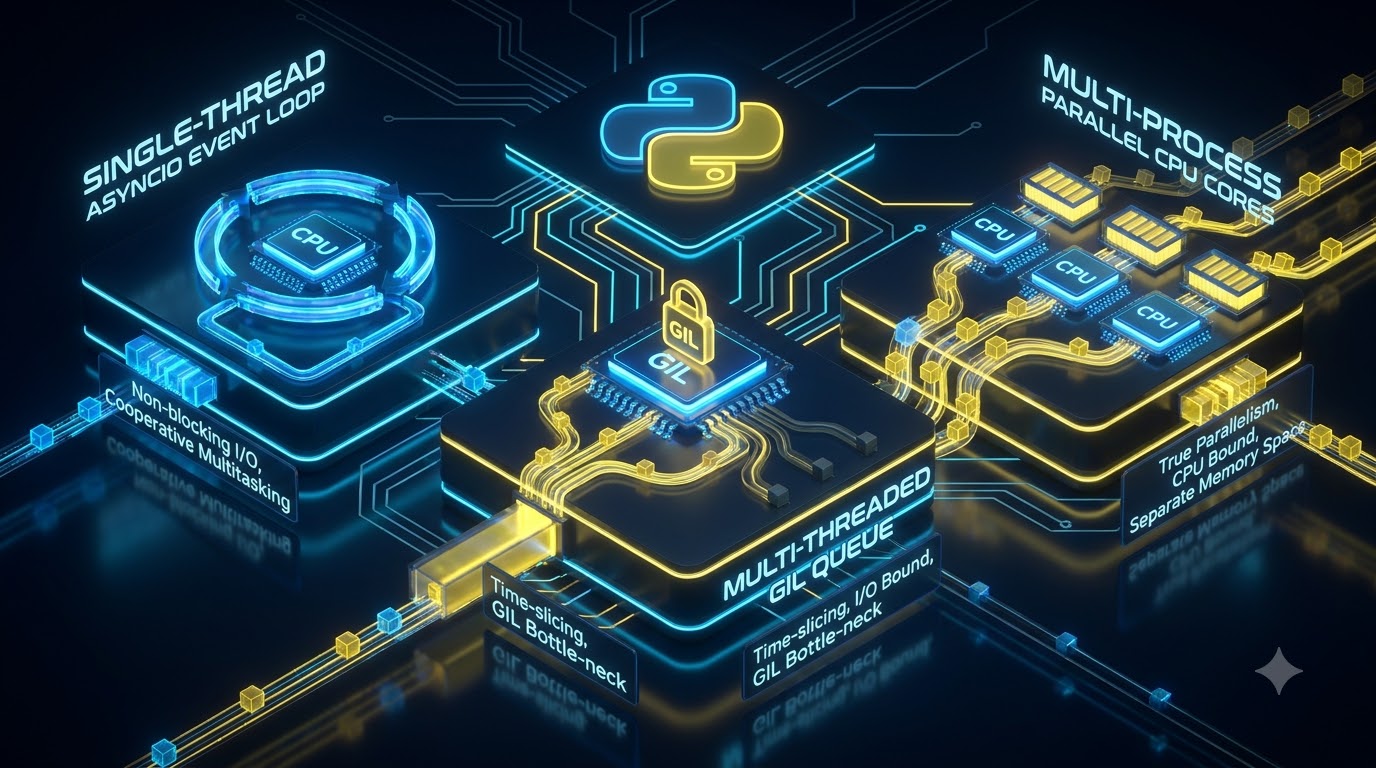
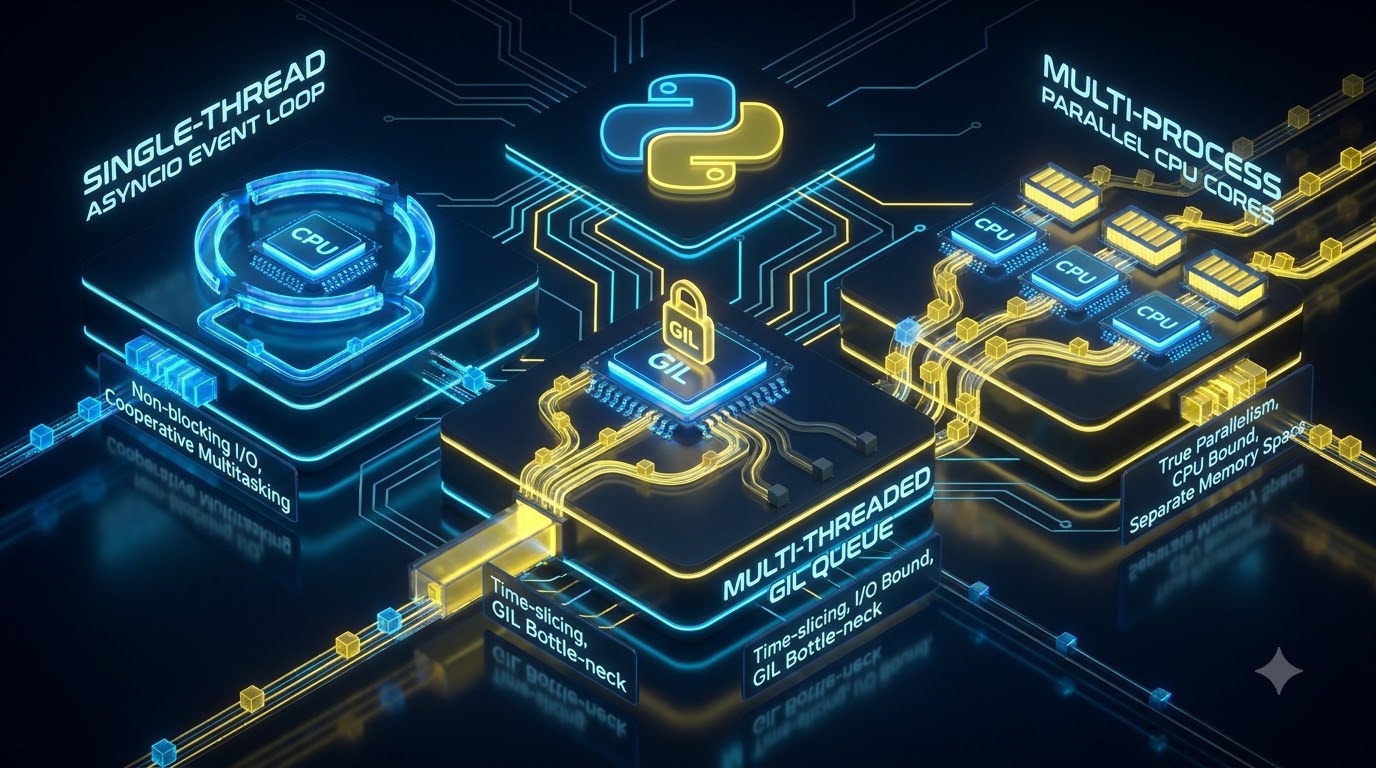
Did you know that adding 4 threads to a CPU-intensive Python calculation often makes it run 30% to 50% slower than a single thread? This counter-intuitive slowdown is caused by constant GIL mutex contention and context switching overhead in CPython.
To write high-performance Python backends, data pipelines, and microservices, you must master the fundamental differences between Threading, Multiprocessing, and AsyncIO Coroutines.
Audio Briefing• Voice: Google Cloud Journey-F
0:00 / --:--
Paradigm Comparison Matrix
| Aspect | AsyncIO (Coroutines) | Threading | Multiprocessing |
|---|---|---|---|
| Concurrency Model | Cooperative single-thread event loop | Preemptive OS threads (1 GIL locked) | Preemptive separate OS processes (Multiple GILs) |
| Memory Model | Shared memory (ultra lightweight) | Shared memory (requires Locks/Mutexes) | Isolated address space (IPC / Pickle serialization) |
| Best Suited For | 10,000+ concurrent network connections / WebSockets | Blocking I/O (legacy DB drivers, file system calls) | Heavy CPU crunching, ML inference, image transforms |
| Resource Overhead | ~1 KB per coroutine (virtually infinite scale) | ~8 KB – 1 MB stack per thread | ~20 MB – 50 MB per process instance |
Architectural Decision Flowchart
Use this decision tree whenever you design concurrent Python systems:
Advertisement
Code in Action: Benchmarking 3 Paradigms
python
import asyncio
import httpx

async def fetch_endpoint(client: httpx.AsyncClient, url: str) -> int:
    response = await client.get(url)
    return response.status_code

async def main():
    urls = ["https://httpbin.org/delay/1"] * 20
    async with httpx.AsyncClient(timeout=10) as client:
        tasks = [fetch_endpoint(client, url) for url in urls]
        # Executes all 20 HTTP calls concurrently in ~1.1 seconds on 1 thread!
        results = await asyncio.gather(*tasks)
        print(f"Fetched {len(results)} endpoints successfully.")

asyncio.run(main())
python
from concurrent.futures import ThreadPoolExecutor
import urllib.request

def blocking_fetch(url: str) -> int:
    # GIL is automatically released during OS socket read
    with urllib.request.urlopen(url, timeout=10) as resp:
        return resp.status

urls = ["https://httpbin.org/delay/1"] * 20
with ThreadPoolExecutor(max_workers=10) as executor:
    results = list(executor.map(blocking_fetch, urls))
    print(f"Threaded fetch completed for {len(results)} URLs.")
python
from concurrent.futures import ProcessPoolExecutor
import math

def cpu_heavy_hash(n: int) -> int:
    # True parallel execution across separate CPU cores without GIL bottleneck
    return sum(math.isqrt(i) for i in range(n))

if __name__ == "__main__":
    numbers = [50_000_000] * 8
    with ProcessPoolExecutor() as executor:
        results = list(executor.map(cpu_heavy_hash, numbers))
        print(f"Parallel CPU computation finished on {len(results)} cores!")
4 Rules to Avoid Concurrency Nightmares
1. Never Mix Blocking Calls Inside AsyncIO
Calling a synchronous blocking function (like time.sleep() or requests.get()) inside an async def function freezes the entire single-threaded event loop for all users! If you must call blocking code, wrap it in await asyncio.to_thread(blocking_func).
2. Protect Shared Memory with Lock Mutexes in Threads
Because threads share memory, non-atomic operations like counter += 1 create severe race conditions. Always synchronize shared state with threading.Lock().
3. Guard Multiprocessing with if __name__ == '__main__':
On Windows and macOS (spawn method), child processes re-import the entry point script. Omitting this guard causes infinite process spawning cascades that crash your system.
4. Minimize Inter-Process Serialization (IPC)
Passing gigabytes of raw data between processes requires costly pickle serialization. Use multiprocessing.shared_memory for zero-copy numpy arrays or memory buffers.
Mental Model Flashcards
CPython Internals
Global Interpreter Lock (GIL)
Click to reveal
CPython Internals
A mutex lock in CPython ensuring only one thread executes Python bytecode at any given moment, protecting memory management from race conditions.
Global Interpreter Lock (GIL)
Concurrency
Cooperative Multitasking
Click to reveal
Concurrency
A concurrency model (used by AsyncIO) where tasks explicitly yield control back to the event loop using the 'await' keyword rather than being interrupted by the OS kernel.
Cooperative Multitasking
Architecture
CPU-Bound vs I/O-Bound
Click to reveal
Architecture
CPU-bound tasks spend time calculating (requires Multiprocessing). I/O-bound tasks spend time waiting on network, disk, or databases (requires AsyncIO or Threads).
CPU-Bound vs I/O-Bound
Interactive Knowledge Check
Interactive Quiz
Why does a single-threaded AsyncIO program handle 10,000 concurrent network sockets faster than 10,000 OS Threads?
Frequently Asked Questions
Yes! Python 3.13+ introduces an experimental --disable-gil (free-threaded Python) build. When enabled, multi-threaded code can execute across multiple CPU cores in parallel without multiprocessing.
Yes! Use loop.run_in_executor(None, sync_function) or asyncio.to_thread(sync_function) to offload blocking legacy synchronous libraries into a background thread pool without stalling the main async event loop.
While Python has no hardcoded limit, practical thread count is constrained by OS virtual memory and kernel thread table limits (typically 1,000 – 2,000 threads before performance degrades drastically).
You Might Also Like
Share this article:
Free Developer Utilities
Free In-Browser Developer Tools
Clean AI CLI logs, build cron expressions, decode JWTs, and calculate chmod permissions offline.
Advertisement
Related Articles
python
Python Async & Concurrency Reference: Event Loop, TaskGroups & Production Patterns (2026)
The definitive production reference for Python asynchronous programming: event loop internals, structured concurrency with TaskGroup, free-threaded CPython 3.13, connection pooling, and profiling event loop starvation.
Read more
python
Python Asyncio Deep Dive: Coroutines, Tasks, and Event Loops in 2026
Master Python asyncio in 2026: Coroutines, TaskGroup vs gather, uvloop internals, preventing event loop starvation, and async semaphore pooling.
Read more
python
Migrating Python Codebases to Free-Threaded CPython 3.13
Audit C extensions, eliminate GIL assumptions, and safely migrate multi-threaded Python workloads to free-threaded CPython 3.13+ for true parallelism.
Read more