Optimizing Python FastAPI for High-Concurrency

Table of Contents
FastAPI has taken the Python web development ecosystem by storm. With its excellent developer experience, automatic Swagger UI generation, and robust data validation powered by Pydantic, it is increasingly the framework of choice for modern Python APIs. However, its most lauded feature is arguably its speed. Benchmarks frequently place FastAPI among the fastest Python frameworks available, rivaling NodeJS and Go in certain scenarios.
But out-of-the-box performance can be deceptive. While a simple "Hello World" benchmark will run blindingly fast, real-world applications dealing with high-concurrency workloads—thousands of simultaneous users, heavy database queries, and external API calls—require careful configuration and architectural forethought. If you deploy a naive FastAPI application into a highly concurrent environment, you might quickly find it buckling under the pressure.
In this extensive guide, we will explore the critical strategies for optimizing Python FastAPI for high-concurrency environments. We will cover process management, the nuances of Python's event loop, database connection pooling, and advanced serialization techniques to ensure your backend scales gracefully.
High-Performance Python Backend Series
1. The Foundation: ASGI and Uvicorn
To understand how to optimize FastAPI, you first need to understand how it runs. Traditional Python web frameworks like Django and Flask were built on WSGI (Web Server Gateway Interface), which is inherently synchronous. FastAPI, on the other hand, is built on ASGI (Asynchronous Server Gateway Interface).
ASGI allows for asynchronous handling of requests, meaning a single server process can handle multiple requests concurrently without waiting for slow I/O operations (like network requests or database reads) to complete.
The standard ASGI server recommended for FastAPI is Uvicorn. Uvicorn is built on top of uvloop (a drop-in replacement for standard asyncio event loops written in Cython) and httptools. This combination is what gives Uvicorn its raw speed.
Typically, you run a FastAPI app during development like this:
uvicorn main:app --reload
While Uvicorn is exceptionally fast, running it like this in production introduces a major bottleneck: a single Uvicorn process is single-threaded. Because of Python's Global Interpreter Lock (GIL), a single Uvicorn process can only ever utilize a single CPU core. On a modern server with 16 or 32 cores, running a single Uvicorn instance leaves the vast majority of your server's computing power completely idle.
2. Scaling Across Cores: Gunicorn with Uvicorn Workers
To harness the full power of a multi-core machine, we need a process manager that can spawn and manage multiple instances of Uvicorn simultaneously. This allows true parallelism (executing multiple operations at the exact same time) to complement our concurrency (managing multiple operations concurrently).
The industry standard process manager for Python web applications is Gunicorn. While Gunicorn is historically a WSGI server, it can be configured to use Uvicorn as its worker class, bringing process management to our ASGI application.
To deploy FastAPI for high concurrency, you should run Gunicorn with Uvicorn workers:
gunicorn -w 4 -k uvicorn.workers.UvicornWorker main:app
Determining the Number of Workers
How many workers should you configure? The classic Gunicorn recommendation for WSGI applications is (2 * number_of_cpu_cores) + 1. However, because ASGI applications are asynchronous and don't block the thread while waiting for I/O, you might not need that many.
A good starting point for FastAPI is one worker per CPU core, perhaps adding one or two extra. For example, on an 8-core machine, you might start with -w 8. The exact number depends heavily on your specific workload (CPU-bound vs. I/O-bound). If your application performs heavy computational tasks, fewer workers might be better to prevent context-switching overhead. Always load-test to find the sweet spot for your infrastructure.
3. The Async/Await Dilemma: async def vs def
This is perhaps the most critical section of this guide. Misunderstanding how FastAPI handles async def versus standard def is the most common cause of catastrophic performance failures in production.
When you define a route using async def, FastAPI runs it directly on the main asynchronous event loop. This is perfect for operations that are non-blocking—such as asynchronous database queries or asynchronous HTTP requests (e.g., using httpx).
# GOOD: Using an async HTTP client inside async def
@app.get("/data")
async def get_data():
    async with httpx.AsyncClient() as client:
        response = await client.get("https://api.example.com")
        return response.json()
However, if you put a synchronous, blocking operation inside an async def route, you will block the entire event loop. While that synchronous operation runs, your server cannot accept or process any other requests. Concurrency drops to zero.
import time

# TERRIBLE: Blocking the event loop
@app.get("/slow")
async def slow_operation():
    time.sleep(5)  # The entire server stops for 5 seconds
    return {"status": "done"}
What if you have to use a synchronous library, like standard requests, standard SQLAlchemy (without async extensions), or a heavy CPU-bound image processing task?
FastAPI provides an elegant solution: use standard def instead of async def. When you use a standard def, FastAPI is smart enough to run that function in an external threadpool. This keeps the main event loop unblocked and responsive, allowing other requests to be processed concurrently.
# GOOD: FastAPI runs this in a threadpool, protecting the event loop
@app.get("/sync-slow")
def slow_sync_operation():
    time.sleep(5)
    return {"status": "done"}
Rule of Thumb:
- Use
async defonly if every single operation inside the function isawait-able and non-blocking. - Use
defif you are using any synchronous database drivers, synchronous API clients, or performing heavy CPU-bound tasks.
4. Database Connection Pooling
In a high-concurrency environment, your application will attempt to talk to your database hundreds or thousands of times a second. Opening a new TCP connection to a database is a slow, expensive operation. Furthermore, databases like PostgreSQL have hard limits on the maximum number of concurrent connections (max_connections).
If your FastAPI application spins up a new connection for every request under heavy load, you will quickly exhaust your database connections and crash the system.
The solution is Connection Pooling. A connection pool maintains a set of active database connections in memory. When a request needs to query the database, it borrows a connection from the pool, runs the query, and returns the connection back to the pool to be reused by the next request.
Implementing Pooling with SQLAlchemy Async
If you are using SQLAlchemy 2.0 with its async extensions, connection pooling is built-in. You configure the pool when you create the engine:
from sqlalchemy.ext.asyncio import create_async_engine

DATABASE_URL = "postgresql+asyncpg://user:password@localhost/dbname"

engine = create_async_engine(
    DATABASE_URL,
    pool_size=20,          # The number of persistent connections to keep open
    max_overflow=10,       # How many additional connections to allow during spikes
    pool_timeout=30,       # How long to wait for a connection before failing
    pool_recycle=1800      # Recycle connections after 30 minutes to prevent staleness
)
For true enterprise scale, relying purely on application-level pooling isn't enough, especially when running multiple Gunicorn workers across multiple servers (since each worker maintains its own pool). In these scenarios, you should implement an infrastructure-level connection pooler like PgBouncer. PgBouncer sits between your FastAPI application and PostgreSQL, multiplexing thousands of application connections down into a handful of actual database connections.
5. Maximizing Throughput: JSON Serialization and Background Tasks
Once your process management and I/O bottlenecks are sorted, you can squeeze out even more performance with application-level optimizations.
Faster JSON Serialization
By default, FastAPI uses Python's standard json library for serialization. While reliable, it's not the fastest. In high-throughput APIs returning large JSON payloads, serialization can become a significant CPU bottleneck.
FastAPI supports custom response classes. You can swap the default JSON response for ORJSONResponse, which uses orjson—an incredibly fast, Rust-based JSON library.
from fastapi import FastAPI
from fastapi.responses import ORJSONResponse

app = FastAPI(default_response_class=ORJSONResponse)

@app.get("/fast-json")
async def get_fast_json():
    return {"message": "This is serialized at the speed of light"}
Just remember to pip install orjson.
Offloading Work with Background Tasks
Never force a user to wait for operations that can happen asynchronously in the background. Sending welcome emails, processing uploaded files, or pinging webhooks should not block an HTTP response.
For simple tasks, use FastAPI's built-in BackgroundTasks. It executes the function after the HTTP response has already been sent to the client.
from fastapi import BackgroundTasks

def send_email_notification(email: str):
    # Simulated email sending
    pass

@app.post("/register")
async def register_user(email: str, background_tasks: BackgroundTasks):
    # Register user in DB...
    background_tasks.add_task(send_email_notification, email)
    return {"message": "User registered successfully"}
For heavy, distributed workloads, integrate a dedicated message queue and task runner like Celery or RQ backed by Redis.
Conclusion
FastAPI is an incredible tool that provides a massive head start in the race for backend performance. However, high concurrency ruthlessly exposes any architectural flaws.
By running FastAPI with Gunicorn workers to scale across cores, rigorously adhering to the rules of Python's event loop (mixing async def and def correctly), implementing robust database connection pooling, and optimizing serialization, you can build backend systems capable of handling millions of requests with ease. Fast by default is good; fast by design is better.
If you've tuned your FastAPI stack and are evaluating whether a different framework architecture could yield higher throughput or lower memory per worker, check out our FastAPI vs Litestar (2026) benchmark comparison.
You Might Also Like
Free In-Browser Developer Tools
Clean AI CLI logs, build cron expressions, decode JWTs, and calculate chmod permissions offline.
Related Articles

SQLite in Production: WAL Mode, High Concurrency, and Battle-Tested PRAGMAs
Master SQLite in high-throughput production environments. Learn Write-Ahead Logging (WAL), busy timeout tuning, concurrent reader/writer limits, and pragmatic benchmarks.
Read more
Advanced Python Data Structures: Stop Using Lists and Dicts for Everything
Pragmatic guide to Python's high-performance data structures: collections.deque, Counter, defaultdict, heapq, and slots dataclasses for 10x faster code.
Read more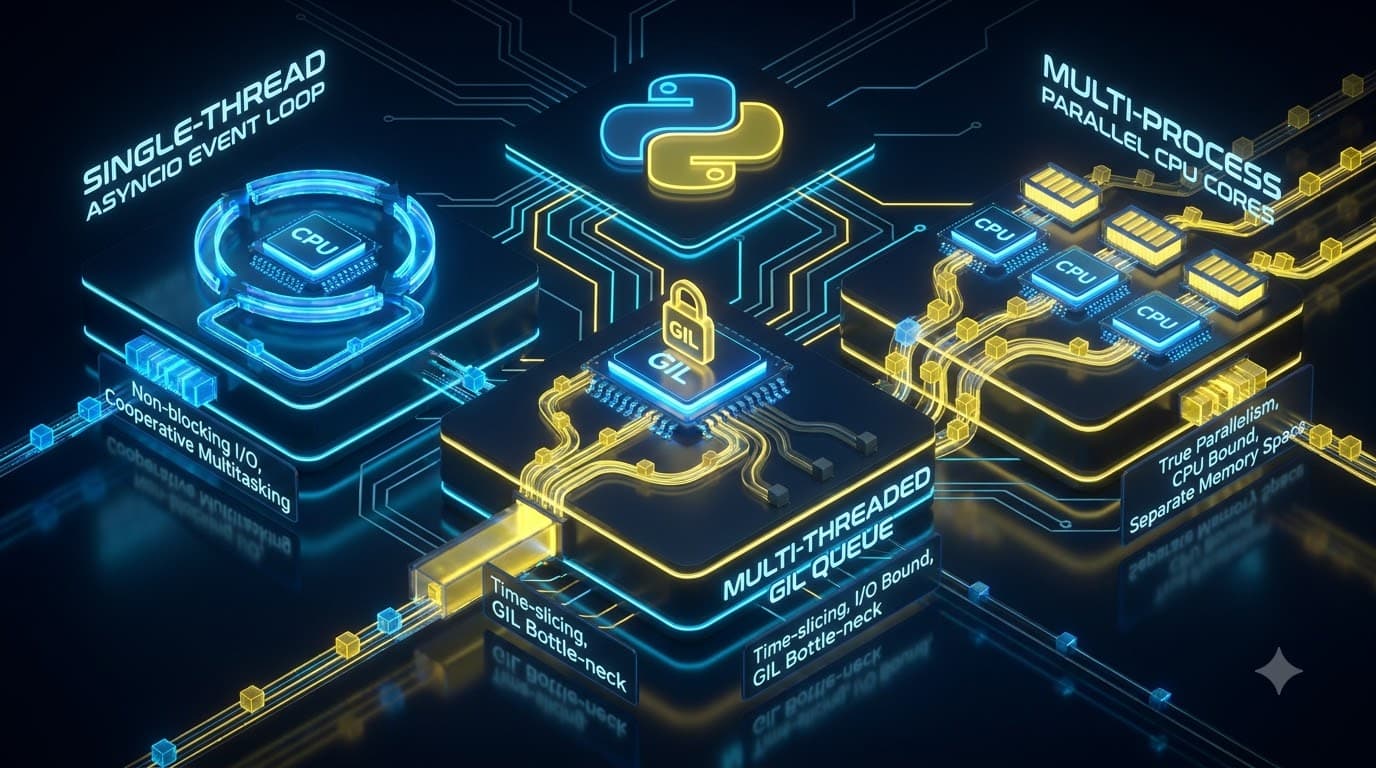
Python Concurrency in 2026: AsyncIO vs Threads vs Processes
Why 4 threads can make CPU code 50% slower. Compare AsyncIO event loops, GIL workarounds, and multiprocessing benchmarks with architectural decision trees.
Read more