Serverless Analytics Warehouse with BigQuery & Cloud Run: From GA4 Streams to Automated SEO Alerts


Table of Contents
Running a high-traffic engineering blog or SaaS product usually leaves you with two flawed analytics choices: either pay $200+/month for heavy observability platforms, or click around manually in Google Analytics 4's confusing interface trying to decipher which blog posts are losing rankings.
There is a superior, production-proven third way: stream raw Google Analytics 4 events directly into BigQuery, run daily scheduled transformations into clean analytical marts, and trigger a serverless Cloud Run job to calculate CTR anomalies and send actionable SEO alerts directly to your Slack or Telegram.
Best of all: because BigQuery provides 1 TB of query processing and 10 GB of storage for free every month, and Cloud Run Jobs only bill while executing (with 0 idle cost), the entire production pipeline costs $0.00/month once your cloud sprint ends.
BigQuery Query Cost & Slot Estimator
Estimate on-demand TB pricing & compute slots before querying
Calculate BigQuery query costs across regions, partition pruning savings, and slot-hour commitments before running expensive analytical warehouse queries.
1. End-to-End Pipeline Architecture
Instead of hosting an always-on PostgreSQL or ClickHouse instance that accrues hourly VM charges, this architecture separates compute from storage completely:
┌─────────────────┐       ┌─────────────────┐       ┌─────────────────────┐
│  Web / App      │       │ Google Analytics│       │ BigQuery Raw Stream │
│  (Next.js Blog) ├──────►│ 4 (GA4 Events)  ├──────►│ `analytics_xxxxxxx` │
└─────────────────┘       └─────────────────┘       │ (Partitioned Tables)│
                                                    └──────────┬──────────┘
                                                               │
                                                 Daily Scheduled Query / View
                                                               │
                                                               ▼
┌─────────────────┐       ┌─────────────────┐       ┌─────────────────────┐
│  Telegram /     │       │ Cloud Run Job   │       │ Curated Mart:       │
│  Slack Alert    │◄──────┤ (Fast Python    │◄──────┤ `daily_seo_dropoffs`│
│  (Actionable)   │       │  Anomaly Worker)│       │ (Summary Table)     │
└─────────────────┘       └─────────────────┘       └─────────────────────┘
Key Components:
- GA4 Native BigQuery Export: Google provides a native, zero-code continuous streaming and daily export from GA4 into BigQuery.
- Partitioned & Clustered Tables: BigQuery tables partitioned by
_PARTITIONDATEand clustered bypage_pathto avoid expensive full-table scans. - Daily Aggregation View: Computes metrics like active users, 0-click impression pages, and bounce rates.
- Cloud Run Job (
min-instances=0): Spun up once daily by Cloud Scheduler. It queries BigQuery, evaluates anomalies (e.g. pages with >500 impressions but <1% CTR), pushes a brief, and terminates immediately.
2. Setting Up Native GA4 Export to BigQuery
In your Google Analytics Admin console:
- Go to Admin → Product Links → BigQuery Links.
- Click Link and select your GCP project (e.g.
project-cf6c933d-0d23-4aae-af7). - Select your cloud region (choose
asia-southeast1orus-central1depending on where your compute sits). - Configure data streams:
- Check Daily export (complete sanitized batch table).
- Check Streaming (within seconds, if you need real-time anomaly detection).
This creates a dataset named analytics_<PROPERTY_ID> in your BigQuery project with tables named events_YYYYMMDD and events_intraday_YYYYMMDD.
3. SQL Data Modeling: Modeling High-Value SEO Queries
Raw GA4 data is heavily nested with repeated records (e.g., event_params.key and event_params.value). Querying raw events directly for every report wastes compute quota.
Here is the production SQL transformation to unnest and create an optimized summary table:
-- Create or replace curated SEO analytics table
CREATE OR REPLACE TABLE `locionic_analytics.daily_post_performance`
PARTITION BY event_date
CLUSTER BY post_slug, locale AS

WITH raw_events AS (
  SELECT
    PARSE_DATE('%Y%m%d', event_date) AS event_date,
    (SELECT value.string_value FROM UNNEST(event_params) WHERE key = 'page_location') AS full_url,
    (SELECT value.int_value FROM UNNEST(event_params) WHERE key = 'ga_session_id') AS session_id,
    user_pseudo_id,
    event_name
  FROM
    `project-cf6c933d-0d23-4aae-af7.analytics_324892182.events_*`
  WHERE
    _TABLE_SUFFIX = FORMAT_DATE('%Y%m%d', DATE_SUB(CURRENT_DATE(), INTERVAL 1 DAY))
),

parsed_pages AS (
  SELECT
    event_date,
    user_pseudo_id,
    session_id,
    REGEXP_EXTRACT(full_url, r'https?://[^/]+/([^/]+)/blog/([^/?#]+)') AS locale,
    REGEXP_EXTRACT(full_url, r'https?://[^/]+/[^/]+/blog/([^/?#]+)') AS post_slug
  FROM
    raw_events
  WHERE
    event_name = 'page_view'
    AND full_url LIKE '%/blog/%'
)

SELECT
  event_date,
  post_slug,
  COALESCE(locale, 'en') AS locale,
  COUNT(1) AS total_views,
  COUNT(DISTINCT user_pseudo_id) AS unique_readers,
  COUNT(DISTINCT session_id) AS total_sessions
FROM
  parsed_pages
WHERE
  post_slug IS NOT NULL
GROUP BY
  event_date,
  post_slug,
  locale;
4. The Cloud Run Anomaly Detection Job
Instead of running an expensive dashboard, a small lightweight Python job runs daily, finds posts with sudden traffic drop-offs, and sends an alert.
Here is the complete production script (analyzer.py):
import os
import json
import requests
from google.cloud import bigquery

PROJECT_ID = os.environ.get("GOOGLE_CLOUD_PROJECT", "project-cf6c933d-0d23-4aae-af7")
TELEGRAM_BOT_TOKEN = os.environ.get("TELEGRAM_BOT_TOKEN")
TELEGRAM_CHAT_ID = os.environ.get("TELEGRAM_CHAT_ID")

def run_anomaly_check():
    client = bigquery.Client(project=PROJECT_ID)

    # Identify pages where views dropped by >40% compared to 7-day average
    query = """
    WITH seven_day_stats AS (
      SELECT
        post_slug,
        AVG(total_views) AS avg_views_7d
      FROM
        `locionic_analytics.daily_post_performance`
      WHERE
        event_date BETWEEN DATE_SUB(CURRENT_DATE(), INTERVAL 8 DAY) AND DATE_SUB(CURRENT_DATE(), INTERVAL 2 DAY)
      GROUP BY post_slug
      HAVING avg_views_7d >= 10
    ),
    yesterday_stats AS (
      SELECT
        post_slug,
        total_views AS views_yesterday
      FROM
        `locionic_analytics.daily_post_performance`
      WHERE
        event_date = DATE_SUB(CURRENT_DATE(), INTERVAL 1 DAY)
    )
    SELECT
      s.post_slug,
      ROUND(s.avg_views_7d, 1) AS avg_7d,
      COALESCE(y.views_yesterday, 0) AS yesterday,
      ROUND(((COALESCE(y.views_yesterday, 0) - s.avg_views_7d) / s.avg_views_7d) * 100, 1) AS pct_change
    FROM
      seven_day_stats s
    LEFT JOIN
      yesterday_stats y ON s.post_slug = y.post_slug
    WHERE
      COALESCE(y.views_yesterday, 0) < (s.avg_views_7d * 0.6)
    ORDER BY
      pct_change ASC;
    """

    query_job = client.query(query)
    results = list(query_job.result())

    if not results:
        print("No traffic anomalies detected today.")
        return

    lines = ["⚠️ *Locionic SEO Alert: Traffic Drop Detected*"]
    for row in results:
        lines.append(f"• `{row.post_slug}`: {row.yesterday} views vs {row.avg_7d} avg ({row.pct_change}%)")

    message = "\n".join(lines)
    print(message)

    if TELEGRAM_BOT_TOKEN and TELEGRAM_CHAT_ID:
        requests.post(
            f"https://api.telegram.org/bot{TELEGRAM_BOT_TOKEN}/sendMessage",
            json={"chat_id": TELEGRAM_CHAT_ID, "text": message, "parse_mode": "Markdown"},
            timeout=10
        )

if __name__ == "__main__":
    run_anomaly_check()
5. Cost Guardrails & Teardown Safety
When building on Google Cloud credits, the danger is leaving services provisioned after credits expire. Here is how to keep this pipeline completely free forever:
- Cloud Run Jobs vs Services:
- Never use
gcloud run deploywithmin-instances > 0. - Use
gcloud run jobs deploy. A job allocates CPU and memory only while executing your Python script (typically 15 to 30 seconds), then automatically scales to zero.
- Never use
- BigQuery Free Tier Protection:
- BigQuery includes 10 GB of active storage and 1 TB of query data processed each month for free.
- For an engineering blog with 1,000 to 10,000 daily events, you consume less than 100 MB of storage per year and less than 1 GB of query scan per month.
- Partition Pruning:
- Always include
WHERE event_date = ...orWHERE _PARTITIONDATE = ...in your queries. Without partition pruning, BigQuery scans every historical partition, needlessly burning query quota.
- Always include
6. Summary Checklist
| Dimension | Traditional Database (Cloud SQL / RDS) | Serverless Warehouse (BigQuery + Cloud Run) |
|---|---|---|
| Monthly Idle Cost | Costs $30-$100/mo even with 0 traffic | $0.00/mo (covered in free tier) |
| Ingestion Bottleneck | Requires connection pool tuning | Native streaming scales to millions of events |
| Maintenance | Storage upgrades, OS patches, vacuuming | Zero maintenance serverless engine |
| Post-Credit Fate | Turns into recurring monthly charges | Operates 100% within GCP free tier forever |
By combining native GA4 streaming, partitioned BigQuery data marts, and event-driven Cloud Run jobs, you create an enterprise-grade analytics engine that monitors your search rankings automatically without costing a single dollar out of pocket.
Free In-Browser Developer Tools
Clean AI CLI logs, build cron expressions, decode JWTs, and calculate chmod permissions offline.
Related Articles
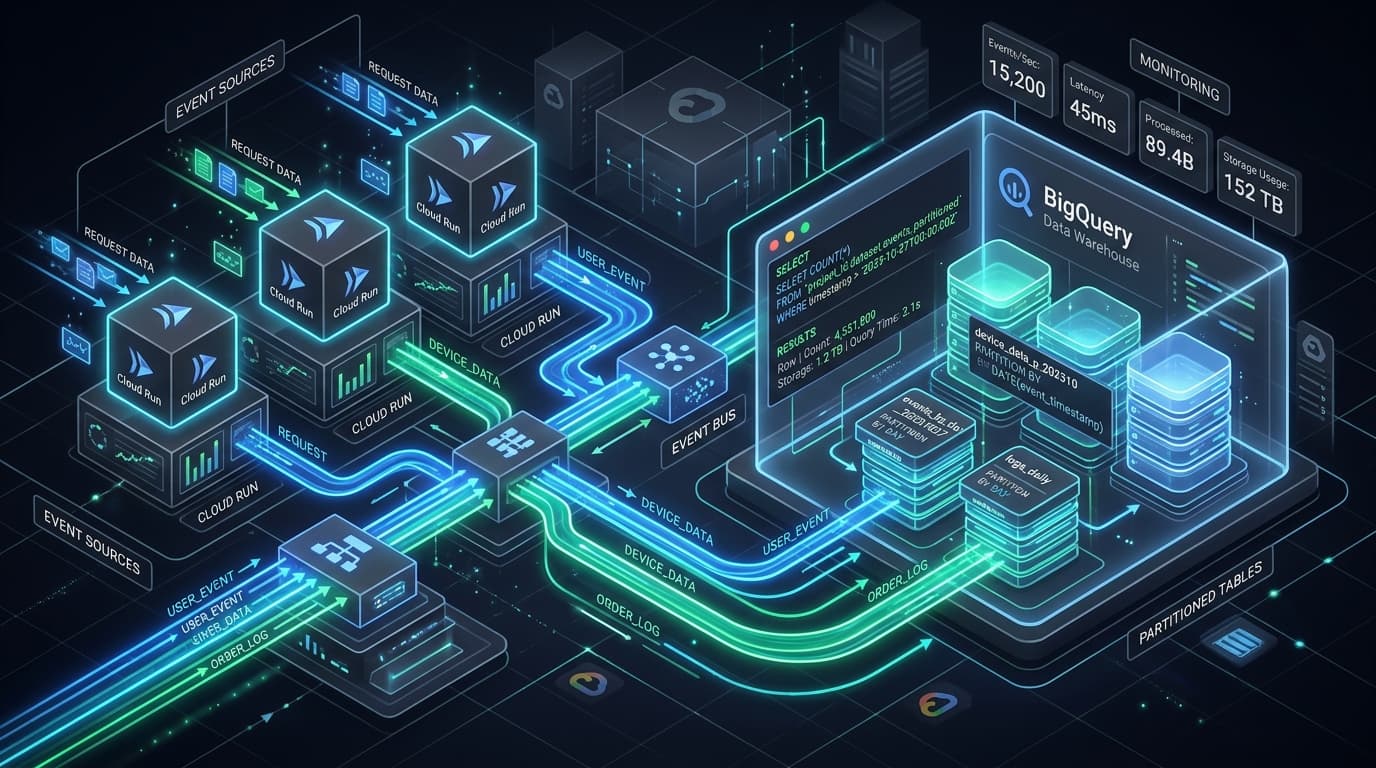
BigQuery + Cloud Run: Building a Production Serverless Data Ingestion Pipeline
A production-grade guide to serverless data ingestion on Google Cloud: the BigQuery Storage Write API, partitioning and clustering strategy, a FastAPI async receiver on Cloud Run, complete Terraform, a real cost breakdown, and the failure modes that page you at 3am.
Read more
The Pragmatic GCP Architecture Guide: Which Services to Actually Use (and What to Avoid)
A battle-tested production guide to Google Cloud Platform. Learn why Cloud Run beats GKE for 90% of workloads, how to leverage BigQuery and Secret Manager, and the 5 hidden cost traps that drain cloud budgets.
Read more
The Hidden Pitfalls of Serverless Architecture
The hidden pitfalls of serverless architectures in 2026: cold start latency, database connection exhaustion, unexpected cloud bills, and mitigations.
Read more