Continuous Dynamic Batching in LLM Inference: Orca, vLLM & TGI Latency Benchmarks
Comprehensive guide covering Continuous Dynamic Batching in LLM Inference: Orca, vLLM & TGI Latency Benchmarks with production-grade architecture and code examples.
Stories, tutorials, and deep dives spanning across diverse worlds.

Comprehensive guide covering Continuous Dynamic Batching in LLM Inference: Orca, vLLM & TGI Latency Benchmarks with production-grade architecture and code examples.

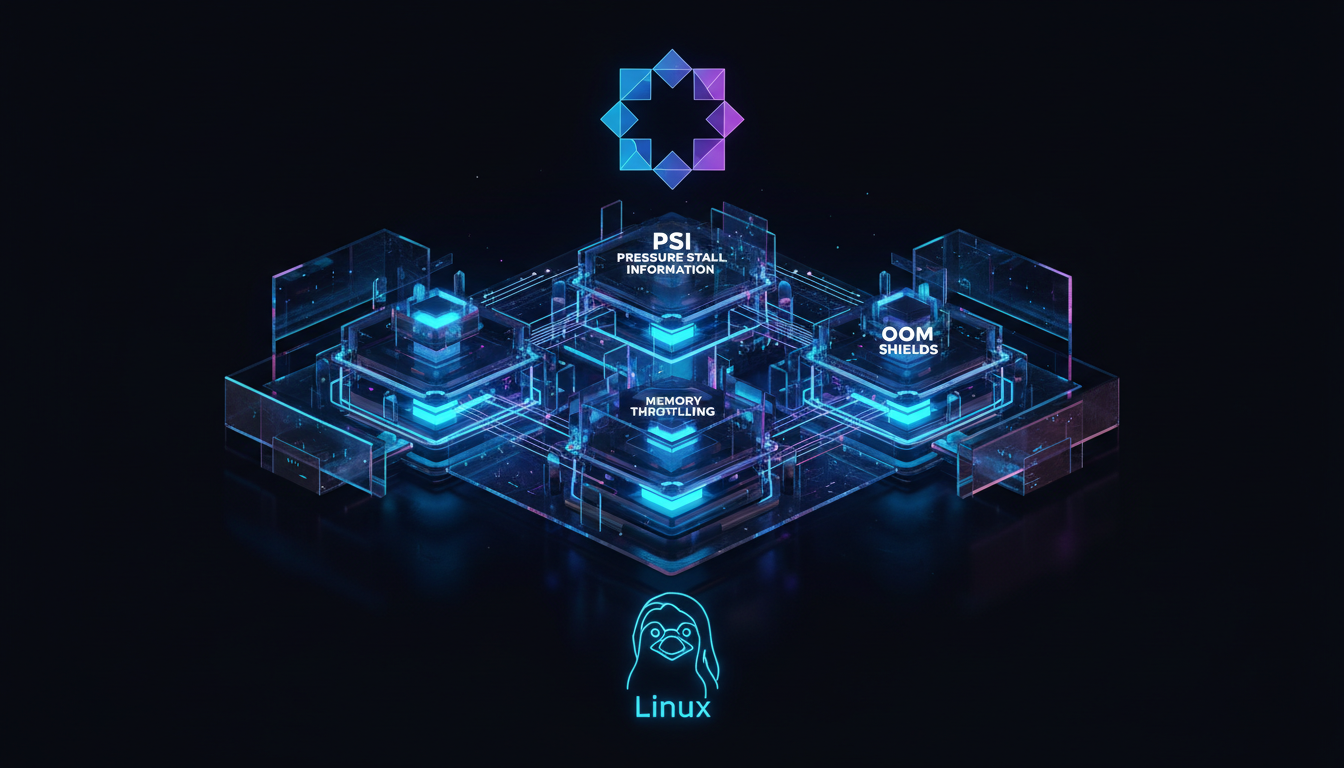
Comprehensive guide covering Linux cgroups v2 in Kubernetes: PSI Pressure Stall Information, Memory Throttling & OOM Shields with production-grade architecture and code examples.
Comprehensive guide covering Real-Time Voice AI: Streaming Whisper Transcription with WebRTC & WebSockets in Rust with production-grade architecture and code examples.
Comprehensive guide covering NVMe-over-TCP in Production: Linux Kernel Architecture, SPDK & High-IOPS Kubernetes Storage with production-grade architecture and code examples.
Comprehensive guide covering High-Throughput Linux I/O in Rust: io_uring, Tokio & Zero-Copy Networking with production-grade architecture and code examples.
Comprehensive guide covering WASI 0.2 & The WebAssembly Component Model: Language-Agnostic Microservices & WIT Interfaces with production-grade architecture and code examples.
Comprehensive guide covering Zig for Systems Programmers: Explicit Memory Allocators, Comptime & C ABI Interop with production-grade architecture and code examples.
Comprehensive guide covering Zero-Knowledge Proofs in Rust & Circom: SnarkJS Verification & Production Guide with production-grade architecture and code examples.
Comprehensive guide covering ScyllaDB vs Apache Cassandra in 2026: P99 Latency, C++ Seastar & TCO Benchmarks with production-grade architecture and code examples.

Implement low-overhead Linux kernel observability using eBPF. Profile system call latency, track memory allocations, and monitor network sockets without sidecars.