Linux cgroups v2 in Kubernetes: PSI Pressure Stall Information, Memory Throttling & OOM Shields
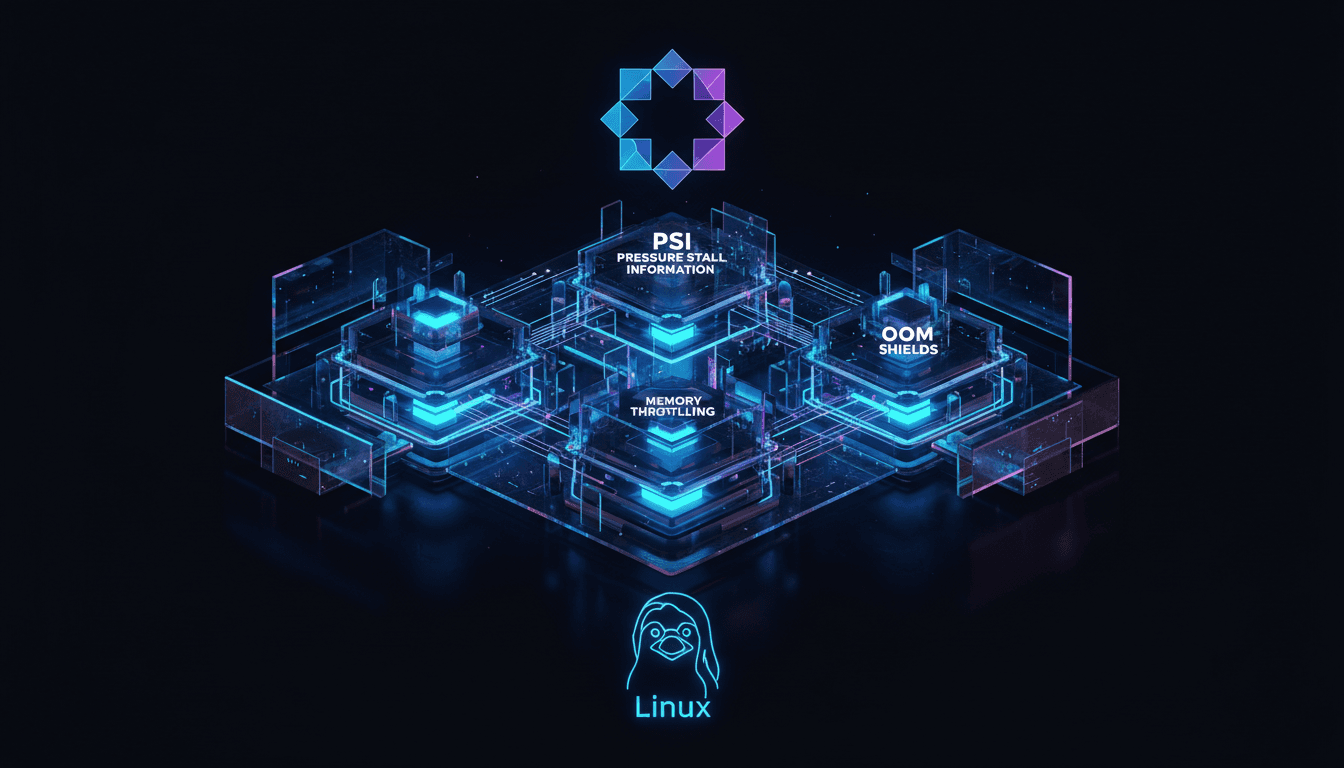

Table of Contents(16 sections)
Linux cgroups v2 represents a fundamental architectural shift in resource management, moving from the fragmented hierarchy of v1 to a unified, tree-like structure. This evolution is critical for modern container orchestration platforms like Kubernetes, enabling more precise and predictable resource isolation. This guide details the operational implications of cgroups v2, focusing on memory management, Pressure Stall Information (PSI), and strategies for OOM protection in Kubernetes.
Cgroups v1 vs. v2: Architectural Paradigm Shift
Cgroups v1 suffered from a fragmented hierarchy problem. Each controller (e.g., cpu, memory, blkio) could have its own independent hierarchy, leading to complex and often conflicting resource assignments for a single process. A process could belong to different cgroups for different resource types, making consistent resource management challenging.
Cgroups v2 introduces a unified hierarchy. All controllers are attached to a single, tree-like hierarchy. A process belongs to exactly one cgroup in this hierarchy, and all resource controllers applicable to that cgroup apply to the process. This simplification provides a more coherent and robust resource management model.
Key Architectural Differences
| Feature | Cgroups v1 | Cgroups v2 |
|---|---|---|
| Hierarchy | Multiple, independent | Single, unified |
| Process Membership | Multiple cgroups (one per controller) | Single cgroup |
| Controller Attachment | Any cgroup | Leaf nodes only (with exceptions) |
| Delegation | Complex, error-prone | Simplified, explicit |
| Resource Files | Inconsistent naming | Standardized naming (cgroup.<controller>.<metric>) |
| Memory Accounting | Less precise | More granular, memory.stat |
| PSI | Not available | Integrated |
The unified hierarchy in v2 simplifies delegation and resource accounting. A parent cgroup can delegate a subtree to a child, granting the child full control over resource management within that subtree without affecting other parts of the hierarchy. This is crucial for container runtimes like containerd and CRI-O, which manage cgroups for individual pods and containers.
Memory Management in Cgroups v2
Cgroups v2 significantly enhances memory management capabilities, introducing memory.high for progressive throttling and refining OOM behavior.
memory.max: The Hard Limit
memory.max defines the absolute memory limit for a cgroup. When a cgroup's memory usage exceeds this value, the kernel's OOM killer is invoked to terminate processes within that cgroup. This is analogous to memory.limit_in_bytes in cgroups v1.
memory.high: The Soft Limit and Throttling Mechanism
memory.high is a crucial addition in cgroups v2. It acts as a soft memory limit. When a cgroup's memory usage exceeds memory.high, the kernel attempts to reclaim memory from that cgroup before reaching memory.max. This is achieved by:
- Page cache eviction: Aggressively dropping clean page cache pages.
- Swap out: Swapping anonymous memory pages to disk (if swap is enabled).
- Direct reclaim: Forcing processes within the cgroup to reclaim memory synchronously.
This progressive throttling mechanism aims to prevent OOM kills by slowing down memory-intensive processes, giving them a chance to reduce their footprint or allowing other processes to free up resources. It provides a more graceful degradation under memory pressure compared to the abrupt OOM kill triggered by memory.max.
Practical Example: Configuring Memory Limits
Consider a Kubernetes Pod with a memory request and limit. Kubernetes translates these into cgroup v2 settings.
apiVersion: v1
kind: Pod
metadata:
  name: memory-intensive-app
spec:
  containers:
  - name: app
    image: busybox
    command: ["sh", "-c", "while true; do sleep 1; done"]
    resources:
      requests:
        memory: "256Mi"
      limits:
        memory: "512Mi"
Assuming a cgroup v2 enabled system and kubelet configured to use cgroups v2, the container runtime (e.g., containerd) will create a cgroup for this pod. The memory.max for the container's cgroup will be set to 512Mi. The memory.high value is typically derived from the memory.request or a percentage of memory.max, depending on the container runtime's configuration. For containerd, memory.high is often set to memory.max by default unless explicitly configured otherwise or if memory.request is specified.
Let's manually inspect cgroup v2 settings for a running container.
# Find the cgroup path for a container (e.g., from a pod named 'memory-intensive-app')
# First, get the container ID
CONTAINER_ID=$(kubectl get pod memory-intensive-app -o jsonpath='{.status.containerStatuses[0].containerID}' | cut -d'/' -f2)

# Assuming containerd, the cgroup path is typically under /sys/fs/cgroup/system.slice/containerd.service/
# and then a path derived from the container ID.
# A more robust way is to use systemd-cgls or findmnt
CGROUP_PATH=$(find /sys/fs/cgroup -name "*${CONTAINER_ID}*" -type d | head -n 1)

echo "Cgroup path: $CGROUP_PATH"

# Read memory limits
cat "${CGROUP_PATH}/memory.max"
cat "${CGROUP_PATH}/memory.high"
cat "${CGROUP_PATH}/memory.current"
cat "${CGROUP_PATH}/memory.stat"
The memory.stat file provides detailed memory accounting, including anon (anonymous memory), file (page cache), kernel_stack, slab, and various other metrics. This granular data is invaluable for debugging memory issues.
Pressure Stall Information (PSI)
PSI is a kernel feature introduced in Linux 4.20 that provides aggregated metrics on how much time tasks spend waiting for CPU, memory, or I/O resources. Unlike traditional metrics that show resource utilization (e.g., CPU usage), PSI quantifies resource contention and starvation. It answers the question: "How much time are my processes stalled because a resource is unavailable?"
PSI metrics are exposed via /proc/pressure/ and within cgroup v2 directories.
PSI Metrics Explained
For each resource (CPU, Memory, I/O), PSI provides three metrics:
some: The percentage of time at least one task was stalled waiting for this resource.full: The percentage of time all tasks were stalled waiting for this resource. This indicates a complete system-wide or cgroup-wide bottleneck.total: The cumulative time (in microseconds) that tasks were stalled.
Example output from /proc/pressure/memory:
some avg10=0.00 avg60=0.00 avg300=0.00 total=0
full avg10=0.00 avg60=0.00 avg300=0.00 total=0
Here, avg10, avg60, avg300 represent the average stall percentage over 10, 60, and 300 seconds, respectively.
PSI in Cgroups v2
Each cgroup v2 directory contains cpu.pressure, memory.pressure, and io.pressure files. These files report PSI metrics specifically for the tasks within that cgroup and its descendants. This allows for fine-grained monitoring of resource contention within individual pods or applications.
# Example: Read memory pressure for a specific cgroup
cat "${CGROUP_PATH}/memory.pressure"
Using PSI for Observability
PSI is a powerful signal for detecting resource bottlenecks before they lead to catastrophic failures like OOM kills or application unresponsiveness.
- High
memory.pressure some: Indicates that some processes within the cgroup are experiencing memory contention. This might be a precursor tomemory.highthrottling or even an OOM kill. - High
memory.pressure full: Suggests that the entire cgroup is severely memory-starved, potentially leading to application freezes. - High
cpu.pressure some: Some tasks are waiting for CPU. Could indicate CPU throttling or an overloaded CPU. - High
io.pressure full: All tasks are waiting for I/O. A clear sign of an I/O bottleneck.
Monitoring PSI metrics in Kubernetes can provide early warnings for resource saturation, enabling proactive scaling or resource adjustment. Prometheus exporters can scrape these metrics from cgroup paths for centralized monitoring.
OOM Shields and systemd-oomd
While memory.high provides a throttling mechanism, severe memory pressure can still lead to OOM kills. In a Kubernetes cluster, critical system daemons (e.g., kubelet, containerd, kube-proxy, node-exporter) must be protected from being OOM-killed by user workloads.
Node Allocatable and Critical Pods
Kubernetes uses the "Node Allocatable" feature to reserve resources for system daemons. This is configured via kubelet flags:
--kube-reserved: Resources reserved for Kubernetes system daemons (e.g.,kubelet,kube-proxy).--system-reserved: Resources reserved for OS system daemons (e.g.,sshd,journald).--eviction-hard: Defines thresholds for eviction.
These reservations ensure that the sum of pod requests does not exceed the allocatable capacity, leaving headroom for critical components. However, this is a scheduling mechanism, not a strict OOM protection. If a user pod consumes more than its limit or if system daemons themselves have a memory leak, OOM can still occur.
systemd-oomd: Proactive OOM Prevention
systemd-oomd is a userspace OOM killer that works in conjunction with cgroups v2 and PSI. Instead of waiting for the kernel OOM killer (which is reactive and often kills the "wrong" process), systemd-oomd monitors cgroups for memory pressure using PSI metrics and memory.high events. When it detects sustained memory pressure, it proactively terminates processes or cgroups that are contributing most to the pressure, based on configurable policies.
systemd-oomd can be configured to:
- Monitor specific cgroups: Protect critical system cgroups.
- Define OOM thresholds: Based on PSI
someorfullpercentages, ormemory.highevents. - Specify kill policies: Which processes to kill first (e.g., largest memory consumer, oldest process).
Example systemd-oomd Configuration (/etc/systemd/oomd.conf)
[OOM]
# Enable oomd
Enable=true

# Global memory pressure thresholds
# If memory.pressure.some reaches 20% for 30s, consider action
MemoryPressureDurationSec=30s
MemoryPressureThreshold=20%

# Action to take when pressure is detected
# Can be 'kill', 'warn', 'none'
DefaultMemoryPressureAction=kill

# Protect system services from being killed by oomd
# This is crucial for Kubernetes nodes
ProtectSystem=true

# Protect specific cgroups (e.g., kubelet)
# This is typically handled by ProtectSystem=true if kubelet is a systemd service
# or by configuring specific cgroup paths.
# Example: Protect the cgroup for kubelet.service
# CGroup=/system.slice/kubelet.service
For Kubernetes, systemd-oomd can be configured to protect the cgroups of kubelet.service, containerd.service, and other critical components. This ensures that even under severe memory pressure from user workloads, the control plane and node infrastructure remain stable.
Integrating systemd-oomd with Kubernetes
- Enable cgroups v2: Ensure your Linux distribution and kernel support and are configured for cgroups v2. Most modern distributions (e.g., Fedora 31+, Ubuntu 20.04+, RHEL 8+) default to or support cgroups v2.
- Verify:
stat -f /sys/fs/cgroupshould showType: cgroup2fs. - Verify
kubeletis running in cgroup v2 mode: Checkkubeletlogs forcgroupfsdriver andsystemdcgroup driver.
- Verify:
- Install and Configure
systemd-oomd: Install thesystemd-oomdpackage. Configure/etc/systemd/oomd.confto protect system services. - Monitor PSI: Integrate PSI metrics into your monitoring stack (e.g., Prometheus Node Exporter). Alert on high
memory.pressurevalues. - Node Allocatable: Properly configure
--kube-reservedand--system-reservedinkubeletto reserve resources for critical components.
Production Gotchas & Troubleshooting
-
Cgroups v1 vs. v2 Mismatch:
- Symptom:
kubeletfails to start or containers fail to launch with cgroup errors.kubectl describe nodeshows cgroup driver warnings. - Cause: The host OS is running cgroups v1, but
kubeletis configured for v2, or vice-versa. Or, the kernel is v2 butkubeletis configured forcgroupfsdriver instead ofsystemd. - Fix: Ensure the host OS is running cgroups v2 (kernel 5.x+). Configure
kubeletto use thesystemdcgroup driver, which is recommended for cgroups v2.Reboot the node after changing cgroup mode if necessary.yaml# /etc/kubernetes/kubelet.conf (or similar kubelet config file) apiVersion: kubelet.config.k8s.io/v1beta1 kind: KubeletConfiguration cgroupDriver: systemd
- Symptom:
-
Aggressive
memory.highThrottling:- Symptom: Applications become unresponsive or experience high latency under moderate memory load, but don't get OOM-killed.
- Cause:
memory.highis set too low, causing premature throttling. This can happen ifmemory.requestis significantly lower than actual working set, andmemory.highis derived frommemory.request. - Fix: Adjust
memory.requestto better reflect the application's typical memory usage. For critical applications, consider settingmemory.highcloser tomemory.maxor disabling it if the application is sensitive to throttling (though this increases OOM risk). Container runtimes like containerd might have configuration options to tune howmemory.highis set.
-
systemd-oomdKilling Unexpected Processes:- Symptom: Critical application processes are killed by
systemd-oomdinstead of user workloads. - Cause:
systemd-oomdconfiguration is too aggressive or doesn't properly exclude critical cgroups. - Fix: Review
oomd.conf. EnsureProtectSystem=trueis set. If specific critical applications are running as user services, ensure their cgroups are explicitly protected or thatoomd's policies prioritize killing less critical workloads. Useoomctlto inspectsystemd-oomd's state and decisions.
- Symptom: Critical application processes are killed by
-
Misinterpreting PSI Metrics:
- Symptom: Alerts fire on PSI metrics, but no actual performance degradation is observed.
- Cause: Misunderstanding the meaning of
somevs.fullor setting alert thresholds too low. Brief spikes insomepressure are often normal. - Fix: Focus on sustained high
fullpressure for critical services. Forsomepressure, look for trends and correlate with other metrics (e.g., latency, error rates). Tune alert thresholds based on observed baseline and acceptable performance degradation.
-
Kernel OOM Killer Still Active:
- Symptom: Despite
systemd-oomdbeing enabled, the kernel OOM killer still intervenes. - Cause:
systemd-oomd's thresholds are not aggressive enough, or the memory pressure escalates too quickly foroomdto react. The kernel OOM killer is the ultimate fallback. - Fix: Adjust
systemd-oomd'sMemoryPressureThresholdandMemoryPressureDurationSecto be more proactive. Ensureoomdis monitoring the correct cgroups. Investigate the root cause of the rapid memory pressure.
- Symptom: Despite
Frequently Asked Questions
-
Why should I migrate to cgroups v2? Cgroups v2 offers a unified hierarchy, simplifying resource management, improving delegation, and providing more granular memory accounting and proactive throttling with
memory.high. It's the future of Linux resource control and is required for features like PSI andsystemd-oomd. Modern Kubernetes versions and container runtimes are increasingly optimized for cgroups v2. -
How does
memory.highdiffer frommemory.max?memory.maxis a hard limit; exceeding it triggers the kernel OOM killer.memory.highis a soft limit; exceeding it triggers proactive memory reclamation and throttling within the cgroup, aiming to prevent reachingmemory.maxand an OOM kill.memory.highprovides a more graceful degradation under memory pressure. -
Can I run Kubernetes with cgroups v1 and
systemd-oomd? No.systemd-oomdrelies heavily on cgroups v2's unified hierarchy and PSI metrics, which are not fully available or consistently exposed in cgroups v1. To leveragesystemd-oomdfor proactive OOM prevention, a cgroups v2 environment is mandatory. -
What are the best practices for setting
memory.requestandmemory.limitwith cgroups v2? Setmemory.requestto the typical working set size of your application. This influencesmemory.highand ensures adequate scheduling. Setmemory.limit(which becomesmemory.max) to the absolute maximum memory your application can consume without causing instability. Avoid settingmemory.limittoo high, as it can lead to resource exhaustion on the node. A common strategy is to setmemory.requestto a value that allows for some burst, andmemory.limitto a value that prevents runaway memory usage. -
How can I monitor PSI metrics in Kubernetes? The Prometheus Node Exporter can expose PSI metrics from
/proc/pressure/and cgroup v2 paths. You can configure Prometheus to scrape these metrics and set up Grafana dashboards and alerting rules based onnode_pressure_cpu_some_total,node_pressure_memory_full_total, and similar metrics for specific cgroups. This provides crucial insights into resource contention.
Free In-Browser Developer Tools
Clean AI CLI logs, build cron expressions, decode JWTs, and calculate chmod permissions offline.
Related Articles
eBPF in Production: Low-Overhead Linux Observability, Tracing, and Kernel Profiling
Implement low-overhead Linux kernel observability using eBPF. Profile system call latency, track memory allocations, and monitor network sockets without sidecars.
Read more
High-Throughput Linux I/O in Rust: io_uring, Tokio & Zero-Copy Networking
Comprehensive guide covering high-throughput linux i/o in rust: io_uring, tokio & zero-copy networking with production-grade architecture and code examples.
Read more
Kubernetes Operators and Custom Resources: Automate Everything
Extend the Kubernetes control plane with Operators and Custom Resource Definitions (CRDs) to automate lifecycle management for complex stateful applications. Learn reconciliation loops, RBAC, testing, and production patterns.
Read more