Kubernetes Operators and Custom Resources: Automate Everything

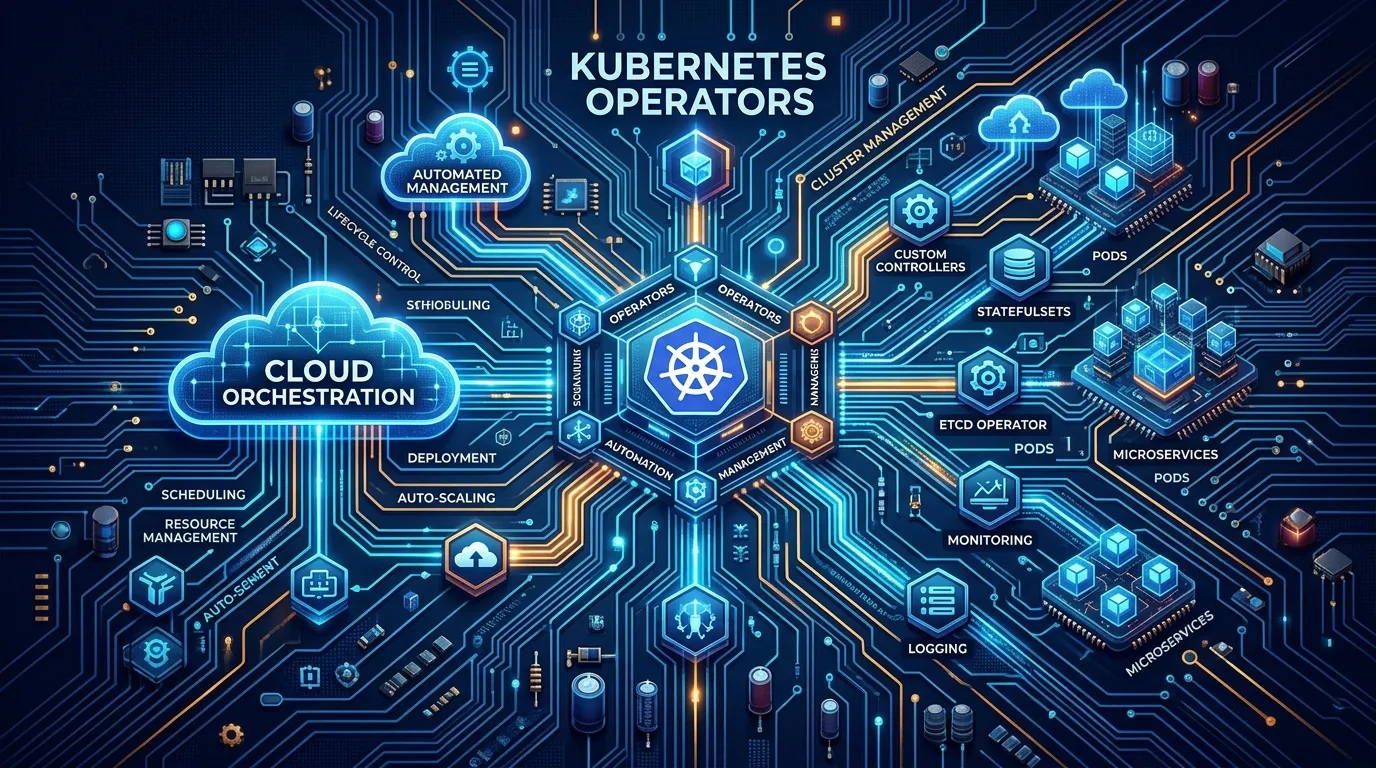
Kubernetes is excellent at managing stateless applications. If a stateless pod dies, a ReplicaSet spins up a new one - no human required. But managing complex stateful applications like databases, message queues, or distributed caches requires domain-specific operational knowledge that Kubernetes doesn't possess by default.
Enter the Operator pattern.
What Is a Kubernetes Operator?
A Kubernetes Operator is a method of packaging, deploying, and managing a Kubernetes application. It takes human operational knowledge - how to back up a Postgres cluster, how to upgrade Kafka without downtime, how to handle replica failover, and encodes it into software that runs natively inside the Kubernetes control plane.
Operationally speaking, an Operator is just a controller that watches one or more Custom Resources and reacts to changes. It runs as a standard Pod inside your cluster and communicates with the Kubernetes API server like any other component.
The concept was introduced by CoreOS in 2016 and has since become a foundational pattern. Today, OperatorHub.io lists hundreds of community and vendor Operators for everything from cert-manager to Prometheus to CockroachDB.
Custom Resource Definitions (CRDs)
Operators rely on Custom Resource Definitions (CRDs) to extend the Kubernetes API surface. A CRD registers a new resource type in your cluster. Instead of only managing Pods, Deployments, and Services, you can define entirely new resource types like PostgresCluster, KafkaTopic, or RedisFailover.
Here's a minimal CRD definition:
apiVersion: apiextensions.k8s.io/v1
kind: CustomResourceDefinition
metadata:
  name: postgresclusters.db.example.com
spec:
  group: db.example.com
  scope: Namespaced
  names:
    plural: postgresclusters
    singular: postgrescluster
    kind: PostgresCluster
  versions:
    - name: v1alpha1
      served: true
      storage: true
      schema:
        openAPIV3Schema:
          type: object
          properties:
            spec:
              type: object
              properties:
                replicas:
                  type: integer
                  minimum: 1
                version:
                  type: string
Once this CRD is applied, users can create PostgresCluster objects using standard kubectl commands:
apiVersion: db.example.com/v1alpha1
kind: PostgresCluster
metadata:
  name: my-db
  namespace: production
spec:
  replicas: 3
  version: "16.2"
The Operator watches for these objects and acts - provisioning PVCs, starting Postgres pods, configuring replication, and managing the full lifecycle.
The Reconciliation Loop
The heart of every Kubernetes Operator is the reconciliation loop (also called the control loop or the reconciler). The loop follows a simple pattern:
- Observe: Watch for changes to the Custom Resource (or any related resource like Pods or ConfigMaps).
- Diff: Compare the desired state (declared in the CR spec) with the current state (what's actually running).
- Act: Take the minimum set of actions needed to converge current state toward desired state.
- Repeat: The loop is idempotent and runs again on any relevant change or after a periodic resync.
This is the same loop Kubernetes itself uses internally for built-in controllers (the Deployment controller, the ReplicaSet controller, etc.). Your Operator is just adding new entries to this loop for your custom resources.
func (r *PostgresClusterReconciler) Reconcile(ctx context.Context, req ctrl.Request) (ctrl.Result, error) {
    log := log.FromContext(ctx)

    // 1. Fetch the PostgresCluster resource
    var cluster dbv1.PostgresCluster
    if err := r.Get(ctx, req.NamespacedName, &cluster); err != nil {
        if errors.IsNotFound(err) {
            // Resource was deleted - clean up external resources
            return ctrl.Result{}, nil
        }
        return ctrl.Result{}, err
    }

    // 2. Reconcile StatefulSet
    if err := r.reconcileStatefulSet(ctx, &cluster); err != nil {
        log.Error(err, "Failed to reconcile StatefulSet")
        return ctrl.Result{RequeueAfter: time.Second * 30}, err
    }

    // 3. Reconcile Service
    if err := r.reconcileService(ctx, &cluster); err != nil {
        log.Error(err, "Failed to reconcile Service")
        return ctrl.Result{RequeueAfter: time.Second * 30}, err
    }

    // 4. Update status
    cluster.Status.ReadyReplicas = r.countReadyReplicas(ctx, &cluster)
    if err := r.Status().Update(ctx, &cluster); err != nil {
        return ctrl.Result{}, err
    }

    return ctrl.Result{RequeueAfter: time.Minute * 5}, nil
}
Key points in the reconciler above:
- Return
ctrl.Result{}with no error when the resource is not found - it was deleted. - Return
ctrl.Result{RequeueAfter: ...}to schedule the next reconciliation without failing. - Always update the status subresource to reflect what's actually running.
- The reconciler must be idempotent: calling it 10 times in a row must produce the same result as calling it once.
Building an Operator: Operator SDK vs controller-runtime
You have two main approaches to building Operators:
1. Operator SDK (recommended for most cases)
The Operator SDK provides scaffolding, code generation, and lifecycle management for Operators. It supports three build approaches:
- Go: Full control, best performance, the standard for production Operators.
- Helm: Wraps an existing Helm chart into an Operator. Good for simple apps.
- Ansible: Uses Ansible playbooks as the reconciliation logic. Good for ops-heavy teams.
Initialize a new Go Operator:
operator-sdk init --domain=example.com --repo=github.com/example/postgres-operator
operator-sdk create api --group=db --version=v1alpha1 --kind=PostgresCluster --resource --controller
This scaffolds:
api/v1alpha1/postgrescluster_types.go: Your CRD Go typescontrollers/postgrescluster_controller.go: Your Reconcilerconfig/crd/: Generated CRD YAMLconfig/rbac/: Generated RBAC rules
2. controller-runtime directly
For maximum control, you can use controller-runtime directly without the SDK scaffolding. This is what the Operator SDK uses under the hood:
mgr, err := ctrl.NewManager(ctrl.GetConfigOrDie(), ctrl.Options{
    Scheme: scheme,
    Metrics: server.Options{BindAddress: ":8080"},
    HealthProbeBindAddress: ":8081",
    LeaderElection: true,
    LeaderElectionID: "postgres-operator.example.com",
})

if err := (&controllers.PostgresClusterReconciler{
    Client: mgr.GetClient(),
    Scheme: mgr.GetScheme(),
}).SetupWithManager(mgr); err != nil {
    setupLog.Error(err, "unable to create controller")
    os.Exit(1)
}
Leader election (LeaderElection: true) is critical in production - it ensures only one replica of your Operator is actively reconciling at any time, preventing split-brain scenarios.
RBAC and Security
Operators need RBAC permissions to watch and modify resources. The Operator SDK generates these automatically, but you should understand what they grant:
apiVersion: rbac.authorization.k8s.io/v1
kind: ClusterRole
metadata:
  name: postgres-operator-role
rules:
  # Watch and manage PostgresCluster CRs
  - apiGroups: ["db.example.com"]
    resources: ["postgresclusters", "postgresclusters/status", "postgresclusters/finalizers"]
    verbs: ["get", "list", "watch", "create", "update", "patch", "delete"]
  # Manage underlying resources
  - apiGroups: ["apps"]
    resources: ["statefulsets"]
    verbs: ["get", "list", "watch", "create", "update", "patch", "delete"]
  - apiGroups: [""]
    resources: ["services", "configmaps", "secrets", "persistentvolumeclaims"]
    verbs: ["get", "list", "watch", "create", "update", "patch", "delete"]
  # Read Pod status for health checks
  - apiGroups: [""]
    resources: ["pods"]
    verbs: ["get", "list", "watch"]
Principle of least privilege: Only grant verbs and resources your Operator actually needs. Avoid cluster-admin bindings.
Finalizers: Clean Up When Resources Are Deleted
When a user deletes a PostgresCluster CR, Kubernetes will remove the CR from etcd, but external resources like cloud storage buckets, load balancers, or external DNS records won't be cleaned up automatically.
Finalizers solve this. They're string markers in the resource's metadata.finalizers field. Kubernetes won't permanently delete a resource until all its finalizers are removed:
const finalizerName = "db.example.com/cleanup"

func (r *PostgresClusterReconciler) handleFinalizer(ctx context.Context, cluster *dbv1.PostgresCluster) error {
    if cluster.DeletionTimestamp.IsZero() {
        // Resource is NOT being deleted - ensure finalizer is registered
        if !controllerutil.ContainsFinalizer(cluster, finalizerName) {
            controllerutil.AddFinalizer(cluster, finalizerName)
            return r.Update(ctx, cluster)
        }
    } else {
        // Resource IS being deleted - run cleanup
        if controllerutil.ContainsFinalizer(cluster, finalizerName) {
            if err := r.cleanupExternalResources(ctx, cluster); err != nil {
                return err
            }
            // Remove finalizer - allows Kubernetes to complete deletion
            controllerutil.RemoveFinalizer(cluster, finalizerName)
            return r.Update(ctx, cluster)
        }
    }
    return nil
}
Always implement finalizers if your Operator creates resources outside the Kubernetes cluster (S3 buckets, Route53 records, Datadog monitors, etc.).
Status Conditions: Communicating Operator State
Rather than using opaque status fields, follow the Kubernetes convention of status conditions - structured, machine-readable status messages:
meta.SetStatusCondition(&cluster.Status.Conditions, metav1.Condition{
    Type:               "Ready",
    Status:             metav1.ConditionTrue,
    ObservedGeneration: cluster.Generation,
    Reason:             "ReconciliationSucceeded",
    Message:            fmt.Sprintf("PostgresCluster with %d replicas is ready", cluster.Spec.Replicas),
})
This produces a kubectl describe output that operators (human ones) can quickly scan:
Conditions:
  Type    Status  Reason                    Message
  ----    ------  ------                    -------
  Ready   True    ReconciliationSucceeded   PostgresCluster with 3 replicas is ready
Testing Your Operator
Unit Testing Reconcilers
Use controller-runtime's fake.NewClientBuilder() to test reconciliation logic without a live cluster:
func TestReconcile_CreatesStatefulSet(t *testing.T) {
    cluster := &dbv1.PostgresCluster{
        ObjectMeta: metav1.ObjectMeta{Name: "test-db", Namespace: "default"},
        Spec:       dbv1.PostgresClusterSpec{Replicas: 3, Version: "16.2"},
    }

    r := &PostgresClusterReconciler{
        Client: fake.NewClientBuilder().
            WithScheme(scheme).
            WithObjects(cluster).
            Build(),
        Scheme: scheme,
    }

    result, err := r.Reconcile(context.Background(), ctrl.Request{
        NamespacedName: types.NamespacedName{Name: "test-db", Namespace: "default"},
    })

    assert.NoError(t, err)
    assert.Equal(t, time.Minute*5, result.RequeueAfter)

    // Verify StatefulSet was created
    var sts appsv1.StatefulSet
    err = r.Get(context.Background(), types.NamespacedName{Name: "test-db", Namespace: "default"}, &sts)
    assert.NoError(t, err)
    assert.Equal(t, int32(3), *sts.Spec.Replicas)
}
Integration Testing with envtest
The envtest package runs a real API server and etcd locally, allowing you to test the full reconciliation flow:
var testEnv *envtest.Environment

func TestMain(m *testing.M) {
    testEnv = &envtest.Environment{
        CRDDirectoryPaths: []string{filepath.Join("..", "config", "crd", "bases")},
    }
    cfg, _ := testEnv.Start()
    // ... setup manager and run tests
    testEnv.Stop()
}
Production Deployment Checklist
Before shipping an Operator to production:
- Leader election enabled: prevents split-brain in multi-replica deployments
- Health probes configured:
/healthzliveness,/readyzreadiness - Metrics exposed: Prometheus metrics at
/metrics(controller-runtime does this automatically) - Finalizers implemented: for any external resource cleanup
- Status conditions: structured, machine-readable status fields
- RBAC least-privilege: no
cluster-admin, no wildcard verbs - CRD validation: OpenAPI v3 schema with required fields and defaults
- Rate limiting: configure
RateLimiteron the controller to prevent API server flooding -
envtestintegration tests passing - OLM bundle: if distributing via OperatorHub
Real-World Operators Worth Studying
| Operator | What it manages | Why study it |
|---|---|---|
| Prometheus Operator | Prometheus + Alertmanager | Excellent CRD design, status patterns |
| Cert-Manager | TLS certificates | Complex finalizer patterns, ACME integration |
| Strimzi | Apache Kafka on Kubernetes | Full stateful lifecycle management |
| CloudNativePG | PostgreSQL clusters | Production-grade Postgres Operator |
Test Your Knowledge
A team is developing a Kubernetes Operator for a complex distributed database. During testing, they observe that the Operator sometimes fails to provision all necessary resources (e.g., PVCs, StatefulSets) when a new Custom Resource (CR) is created, especially under high cluster load or API server latency. Which of the following is the most robust design principle to ensure eventual consistency and resilience in the Operator's reconciliation logic?
Frequently Asked Questions
Should I write an Operator or just use Helm? Helm is great for simple, stateless deployments. Use an Operator when your application has operational logic that needs to run continuously - failover decisions, schema migrations, backup scheduling, cluster scaling policies. If it would require a cron job or a human to manage it, it's a candidate for an Operator.
Can I write an Operator without Go? Yes. The Operator SDK supports Helm and Ansible as backend languages. For Python, kopf is a popular framework. However, Go gives you the best performance, tooling, and alignment with the rest of the Kubernetes ecosystem.
How many CRDs should one Operator manage? Keep it focused. An Operator that manages one well-defined domain (e.g., a specific database) is easier to maintain and test than a God-Operator that manages everything. The single responsibility principle applies here.
What's the difference between an Operator and a controller? Technically, every Operator is a controller, but not every controller is an Operator. The "Operator" term specifically refers to controllers that encode operational domain knowledge about a specific application. A controller that manages generic infrastructure is usually just called a controller.
Wrapping Up
Kubernetes Operators transform your cluster from a container scheduler into a fully self-healing platform for complex workloads. The pattern scales from simple Helm-based Operators to sophisticated Go controllers that manage database failover, certificate rotation, and multi-cluster replication automatically.
The investment in writing an Operator pays off when you're managing 10+ instances of a stateful application and human operational work becomes the bottleneck. At that scale, encoded operational knowledge running 24/7 inside the cluster is infinitely more reliable than runbooks and on-call engineers.
You Might Also Like
Free In-Browser Developer Tools
Clean AI CLI logs, build cron expressions, decode JWTs, and calculate chmod permissions offline.
Related Articles
Kubernetes Operators: Building Custom Controllers with the Operator SDK
A practical guide to building production Kubernetes operators with the Operator SDK and Kubebuilder in Go: CRD scaffolding, idempotent reconcile loops, finalizers, and envtest integration suites.
Read more
Building Kubernetes Operators in Go: Managing Stateful Applications
Step-by-step tutorial on building production Kubernetes Operators in Go using Kubebuilder to manage stateful workloads and custom resources.
Read more
Kubernetes Custom Resource Definitions
Design and deploy Kubernetes Custom Resource Definitions (CRDs) with Go operators: automate cloud-native infrastructure and reconcile state loops.
Read more