System Design: Building a Distributed Rate Limiter
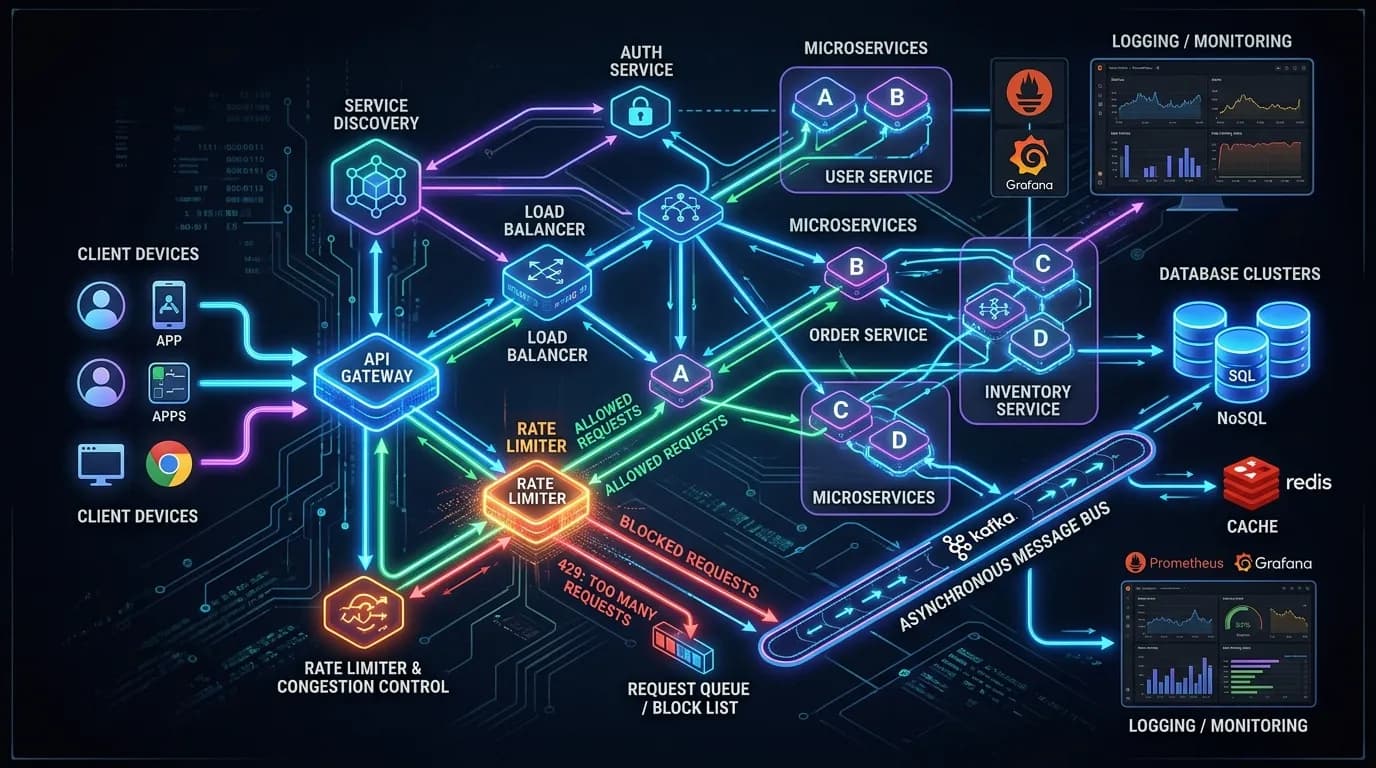

Table of Contents
Introduction
Any public-facing API requires rate limiting. Without it, your system is vulnerable to brute-force attacks, DDoS attempts, and noisy neighbor problems where a single aggressive client degrades the experience for everyone else.
Designing a rate limiter for a single server is relatively simple. Designing one for a globally distributed microservices architecture handling millions of requests per second is a classic system design challenge. In this article, we'll break down the architecture and algorithms required.
1. Choosing the Right Algorithm
The heart of a rate limiter is the algorithm it uses to count requests.
Token Bucket
- How it works: Imagine a bucket holding tokens. Tokens are added at a fixed rate. Every request costs one token. If the bucket is empty, the request is dropped.
- Pros: Memory efficient, allows for short bursts of traffic.
- Cons: Tricky to tune burst size vs. sustained rate.
Fixed Window Counter
- How it works: Divides time into fixed windows (e.g., 12:00 to 12:01). Increments a counter for every request. Resets at the start of the next window.
- Pros: Very easy to implement.
- Cons: Spike traffic at the edges of the window. A client could send their entire quota at 12:00:59 and again at 12:01:01, effectively doubling their allowed rate in a short span.
Sliding Window Log
- How it works: Keeps a timestamp log of every request for a user. Drops requests if the log size exceeds the limit within the time frame.
- Pros: Highly accurate.
- Cons: Consumes significant memory and compute to maintain and prune logs. Not viable for massive scale.
Sliding Window Counter (The Winner)
- How it works: A hybrid approach. It tracks the counter for the previous fixed window and the current fixed window, and calculates a weighted average based on the current time overlapping the window.
- Pros: Smooths out edge spikes, highly memory efficient, highly accurate.
2. Architecture for Distributed Systems
In a multi-server setup, maintaining state becomes the primary challenge. If a load balancer routes User A's first request to Server 1 and their second to Server 2, how do they share the rate limit counter?
Option A: Sticky Sessions
Route all traffic for a specific user to the same server. The server keeps the rate limit state in local memory.
- Verdict: Bad idea. It unevenly distributes load and fails gracefully when a server crashes.
Option B: Centralized Datastore (Redis)
All servers read and write to a centralized Redis cluster. Redis is fast enough (in-memory) to handle the latency requirements.
- Verdict: The standard approach. However, it introduces network latency and race conditions.
3. Handling Race Conditions in Redis
If two requests for the same user hit two different API servers simultaneously, both might read the counter as 4, both increment to 5, and both allow the request, bypassing the limit.
Solution: Lua Scripts
Redis allows you to execute Lua scripts atomically. You can write a script that fetches the counter, checks the limit, increments it, and updates the TTL in a single atomic operation.
-- Simple Token Bucket Lua Script
local key = KEYS[1]
local limit = tonumber(ARGV[1])
local current = tonumber(redis.call('get', key) or "0")

if current + 1 > limit then
    return 0 -- Rejected
else
    redis.call('INCRBY', key, 1)
    redis.call('EXPIRE', key, 60)
    return 1 -- Allowed
end
4. Performance Optimization: Local Cache + Async Sync
For ultra-high throughput where even Redis latency is unacceptable, you can use a hybrid approach.
- API servers keep a local, in-memory rate limiter.
- They sync their local counts to the central Redis cluster asynchronously every few seconds.
- Tradeoff: This trades strict accuracy for performance. A client might exceed their limit slightly between sync windows, but the system remains highly available and fast.
Conclusion
Building a distributed rate limiter requires balancing strict enforcement against system latency. For most modern APIs, combining a Sliding Window algorithm implemented via atomic Redis Lua scripts provides the best balance of accuracy, performance, and scalability.
Deep Dive: The Core Mechanics
When we look beneath the surface, the underlying mechanics reveal a complex interplay of systems. In modern development, understanding these mechanics is what separates a novice from an expert.
Consider this practical example:
// A comprehensive example demonstrating advanced patterns
class ServiceManager {
  constructor() {
    this.services = new Map();
    this.initialized = false;
  }

  register(name, service) {
    if (this.services.has(name)) {
      throw new Error(`Service ${name} already registered`);
    }
    this.services.set(name, service);
  }

  async initializeAll() {
    this.initialized = true;
    for (const [name, service] of this.services) {
      if (typeof service.init === 'function') {
        await service.init();
      }
    }
  }

  get(name) {
    if (!this.initialized) {
      console.warn('Accessing services before initialization');
    }
    return this.services.get(name);
  }
}
This pattern ensures that our architecture remains scalable and robust even as business requirements change. It's a fundamental approach that pays dividends in large-scale applications.
Real-world Application and Scaling
Implementing this in a production environment introduces a new set of challenges. We must account for concurrency, state management, and memory leaks.
For instance, when dealing with high-throughput systems, every micro-optimization counts. We often rely on profiling tools to identify bottlenecks that aren't apparent during local development.
The diagram above illustrates a typical deployment strategy where our application scales horizontally.
Test Your Understanding
You Might Also Like
- How to Harden Firefox on Linux (Beginner's Guide)
- VPN vs Proxy: Differences, Fingerprinting, Leaks, and Privacy Testing
- The 5 Best Playwright Alternatives for E2E Testing in 2026
- Cypress to Playwright Migration Consulting: How to Upgrade Your Testing Strategy
Frequently Asked Questions
Free In-Browser Developer Tools
Clean AI CLI logs, build cron expressions, decode JWTs, and calculate chmod permissions offline.
Related Articles
Redis Memory Optimization: Internals, Data Structure Encoding, and Memory Profiling
Slash your Redis RAM usage by up to 70%. Deep dive into ziplists, listpacks, quicklists, string SDS overhead, and automated memory fragmentation mitigation.
Read more
FastAPI vs Celery (2026): BackgroundTasks vs Distributed Queues
FastAPI BackgroundTasks vs Celery: architectural trade-offs, event-loop blocking risks, Redis message brokers, memory benchmarks, and when to switch.
Read more
Platform Engineering: Building Golden Paths for Developers
How to build Internal Developer Platforms (IDPs) and Golden Paths that reduce cognitive load, automate CI/CD pipelines, and scale platform engineering.
Read more