Kubernetes HPA with Custom Prometheus Metrics: Beyond CPU Scaling (2026)
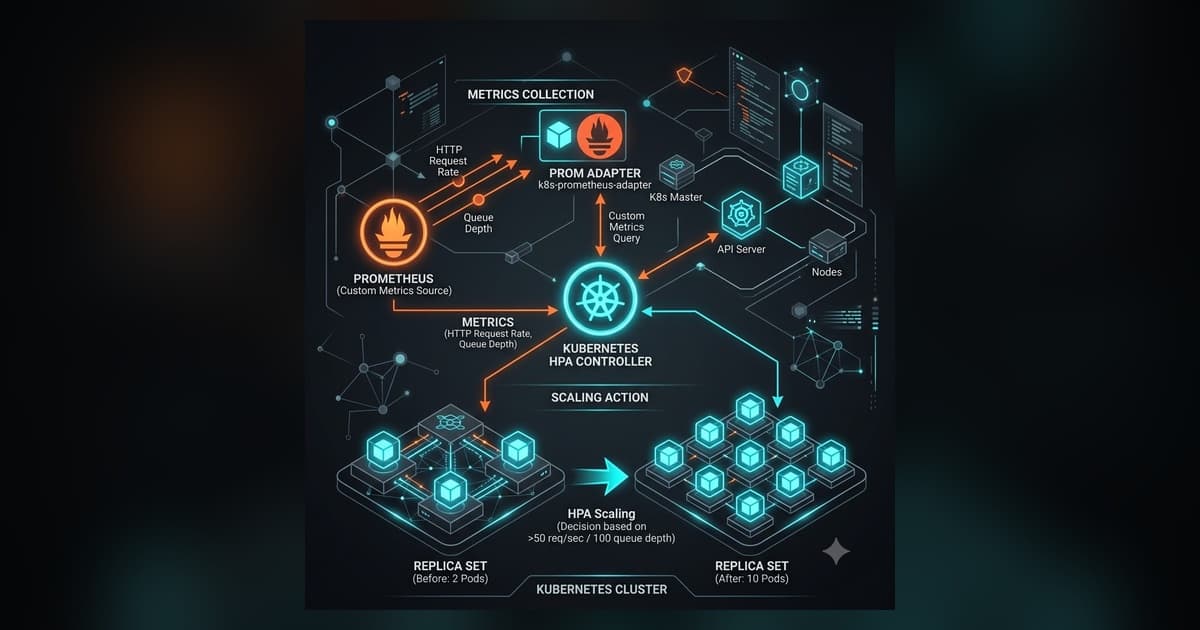

Table of Contents
- How Custom Metric Autoscaling Works
- How Do You Configure Prometheus Adapter Rules for Custom Metrics?
- How Do You Define an HPA Manifest Using Custom Prometheus Metrics?
- How Do You Troubleshoot Custom Metrics API Errors and HPA Failure Modes?
- How Do You Tune HPA Scaling Behavior and Stabilization Windows?
- How Do You Monitor HPA Performance Metrics in Production Grafana Dashboards?
- You Might Also Like
- Frequently Asked Questions
For a long time, we scaled our Kubernetes pods the standard way: when CPU or memory hit 80%, we added more replicas. It worked fine until we noticed our APIs were timing out due to request backlogs, even though CPU usage was hovering around 40%.
Standard node resource metrics often don't tell the whole story. Your app might be starved for worker threads or drowning in a message queue while the CPU looks completely healthy. The fix? Connecting the Kubernetes Horizontal Pod Autoscaler (HPA) directly to our Prometheus application metrics so we could scale based on actual traffic demands, like HTTP requests per second.
How Custom Metric Autoscaling Works
Scaling on custom metrics sounds like black magic at first, but it's just plumbing. The HPA queries the Custom Metrics API aggregation layer, which routes requests to an adapter (like the Prometheus Adapter). This adapter translates raw Prometheus time-series data into Kubernetes metric objects.
When the HPA wakes up every 15 seconds, it queries custom.metrics.k8s.io. The adapter runs your PromQL query, returns the current value, and the HPA calculates if it needs to spin up new pods.
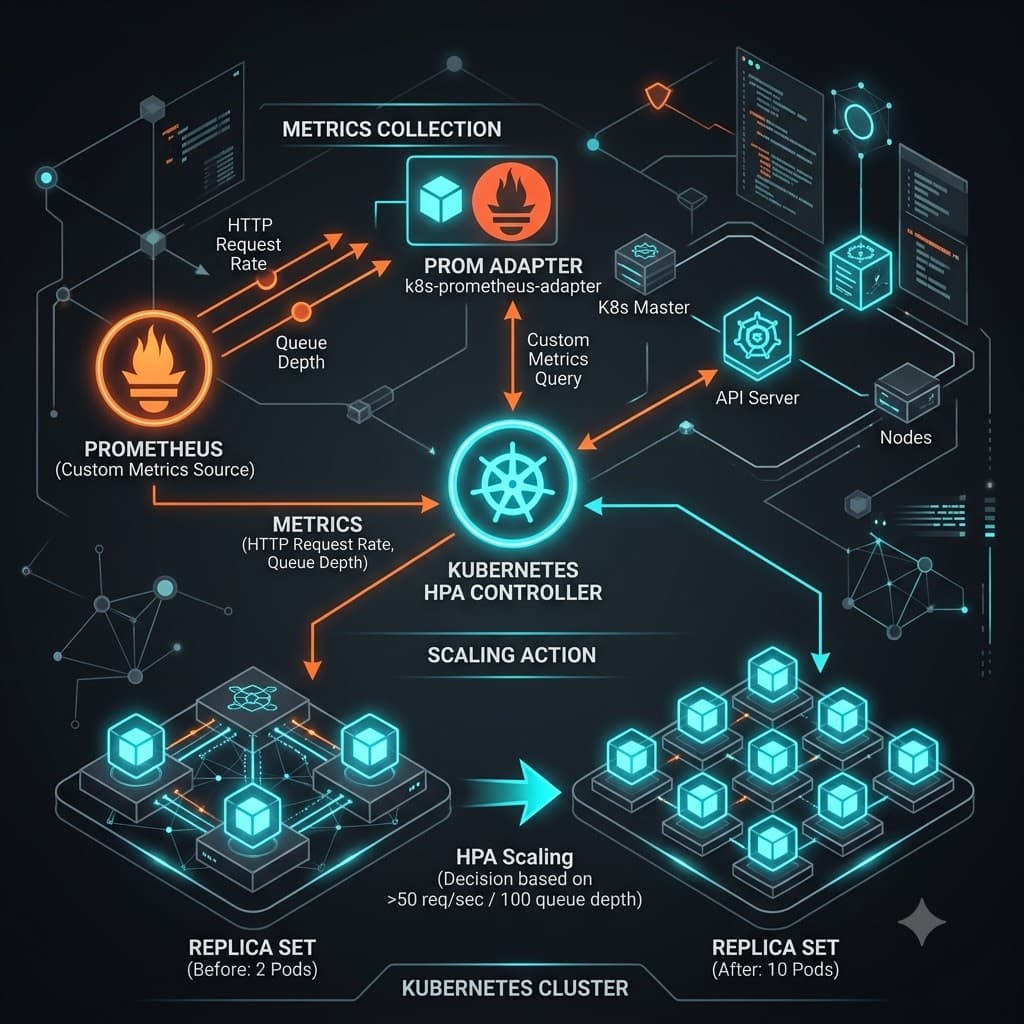
Understanding the internal control flow prevents common architectural mistakes during cluster setup. The Kubernetes control plane doesn't scrape application endpoints directly. Instead, your application exposes Prometheus formatted metrics at an HTTP endpoint like /metrics. Prometheus continuously scrapes these endpoints, stores the time-series records in its local storage database, and makes them available for querying. The Prometheus Adapter acts as an API extension server that implements the custom.metrics.k8s.io/v1beta1 interface. It regularly executes registered PromQL queries against your Prometheus server, caches the calculation results, and responds to API requests initiated by the Horizontal Pod Autoscaler controller.
To ensure deterministic scaling behavior, the custom metric values must be associated with specific Kubernetes resources like Pods, Namespaces, or Services. The API server enforces strict label matching between the metric definition and the target workload selectors. If your application metric lacks pod name labels or namespace identification, the adapter can't map the scalar value back to individual pod instances. This decoupling ensures that cluster control loops remain isolated from specific monitoring vendors while giving platform operators complete flexibility to write sophisticated PromQL queries.
Here's an architectural overview of how telemetry metrics flow through the control plane components during a scaling decision:
+------------------+         Scrapes         +--------------------+
| Application Pod  | <---------------------- | Prometheus Server  |
|  (/metrics)      |                         |  (TSDB Storage)    |
+------------------+                         +--------------------+
         ^                                             ^
         |                                             | PromQL Queries
         | Managed By                                  v
+------------------+     Queries API         +--------------------+
| HPA Controller   | ----------------------> | Prometheus Adapter |
| (Control Loop)   |  custom.metrics.k8s.io  | (API Extension)    |
+------------------+                         +--------------------+
How Do You Configure Prometheus Adapter Rules for Custom Metrics?
You configure Prometheus Adapter rules for custom metrics by editing the adapter configuration Map to define series matching regex patterns, resource associations, metric naming templates, and explicit PromQL aggregation queries. The configuration file governs how raw Prometheus metric series translate into queryable Kubernetes API endpoints. Without explicit adapter rules, the API server won't expose your custom application metrics to the Horizontal Pod Autoscaler controller.
The configuration file consists of four primary sections for every rule block: seriesQuery, resources, name, and metricsQuery. The seriesQuery selects candidate time-series from Prometheus matching specific metric name patterns and label key presence. The resources block maps Prometheus metric labels like kubernetes_pod_name or namespace to Kubernetes API resource types like pod and namespace. The name block renames the raw Prometheus metric into a clean metric name presented by the custom metrics API. Finally, the metricsQuery defines the exact PromQL expression used to aggregate metrics when the autoscaler requests scalar values.
Let me show you a complete, production-ready Helm values.yaml configuration block for Prometheus Adapter that transforms raw HTTP request rates into a pod-level metric:
rules:
  default: false
  custom:
    - seriesQuery: 'http_requests_total{kubernetes_pod_name!="",kubernetes_namespace!=""}'
      resources:
        overrides:
          kubernetes_namespace: {resource: "namespace"}
          kubernetes_pod_name: {resource: "pod"}
      name:
        matches: "^(.*)_total"
        as: "${1}_per_second"
      metricsQuery: 'sum(rate(<<.Series>>{<<.LabelMatchers>>}[2m])) by (<<.GroupBy>>)'
    - seriesQuery: 'queue_depth_messages{kubernetes_pod_name!="",kubernetes_namespace!=""}'
      resources:
        overrides:
          kubernetes_namespace: {resource: "namespace"}
          kubernetes_pod_name: {resource: "pod"}
      name:
        matches: "^(.*)"
        as: "queue_depth_messages"
      metricsQuery: 'sum(<<.Series>>{<<.LabelMatchers>>}) by (<<.GroupBy>>)'
Notice how template variables like <<.Series>>, <<.LabelMatchers>>, and <<.GroupBy>> dynamicize the query evaluation. When the HPA requests the metric http_requests_per_second for pods in the default namespace, the Prometheus Adapter substitutes <<.Series>> with http_requests_total, populates <<.LabelMatchers>> with pod name filters, and sets <<.GroupBy>> to kubernetes_pod_name. This automatic parameter substitution allows a single rule pattern to serve hundreds of distinct microservices running across your cluster without writing boilerplate queries for every application.
When defining metricsQuery, you should always use rate functions over short time windows like two minutes rather than instantaneous gauge values for counter metrics. Raw counter values continuously increment over time, making them unsuitable for direct target thresholds. Applying rate() converts raw counters into per-second rates that reflect real-time workload throughput. Furthermore, setting default: false in your Helm configuration prevents the adapter from automatically discovering thousands of unused cluster metrics, which dramatically reduces CPU overhead and memory consumption on the adapter pods.
How Do You Define an HPA Manifest Using Custom Prometheus Metrics?
You define an HPA manifest using custom Prometheus metrics by specifying v2 as the apiVersion, selecting Pods or Object as the metric source type, and setting target metric thresholds in the metrics array. The Kubernetes autoscaling/v2 API specification provides native support for multiple metric types including resource, custom pod, object, and external metrics. When targeting pod-level custom metrics, you must select type: Pods and set metric.name to match the exact name exposed by your Prometheus Adapter rule.
In the HPA manifest spec, type: Pods tells the controller that the metric value represents a per-pod metric that must be averaged across all active pods in the target workload. The metric target must use type: AverageValue with a quantity like 50 or 500m (which represents 0.5 requests per second). The autoscaler sums the metric values across all running pods, divides by the current replica count, and compares the result against your specified target average value to decide whether to scale out or scale in.
Here's a production manifest that scales an API deployment based on HTTP request throughput per pod:
apiVersion: autoscaling/v2
kind: HorizontalPodAutoscaler
metadata:
  name: api-service-hpa
  namespace: production
spec:
  scaleTargetRef:
    apiVersion: apps/v1
    kind: Deployment
    name: api-service
  minReplicas: 3
  maxReplicas: 30
  metrics:
    - type: Pods
      pods:
        metric:
          name: http_requests_per_second
        target:
          type: AverageValue
          averageValue: "35"
If you need to scale your deployment based on an un-namespaced resource or an external system like an AWS SQS queue or Redis list depth, you should use type: External or type: Object instead of type: Pods. For instance, when scaling a background queue worker deployment, the metric value reflects the total length of the queue rather than a value measured inside individual worker pods. In that scenario, setting type: Value under an Object or External target allows the HPA to divide total queue length by the desired workload processing capacity per pod.
Combining multiple metric sources in a single HPA manifest provides dependable fail-safe scaling guarantees for mission-critical deployments. When multiple metrics are configured in the metrics array, the Horizontal Pod Autoscaler calculates the proposed replica count for each metric independently and picks the highest calculated replica count. This means if CPU utilization suddenly spikes due to a expensive garbage collection cycle while request rates remain low, the HPA will still scale up pods to protect service availability.
  metrics:
    - type: Resource
      resource:
        name: cpu
        target:
          type: Utilization
          averageUtilization: 75
    - type: Pods
      pods:
        metric:
          name: http_requests_per_second
        target:
          type: AverageValue
          averageValue: "35"
How Do You Troubleshoot Custom Metrics API Errors and HPA Failure Modes?
You troubleshoot Custom Metrics API errors by querying the raw custom metrics REST API endpoint with kubectl get --raw, checking Prometheus Adapter logs for PromQL execution failures, and describing the HPA resource to inspect status conditions. When the HPA reports unable to fetch metric or invalid metric value, the issue almost always lies in label matching mismatches or adapter configuration errors. Direct API queries allow you to isolate whether the failure stems from Prometheus data ingestion, adapter query translation, or Kubernetes RBAC permissions.
The first step in diagnosing custom metrics failures is verifying that the extension API server is registered and healthy within the Kubernetes control plane. Running kubectl get apiservices v1beta1.custom.metrics.k8s.io should display AVAILABLE: True. If the status shows false or degraded, check whether the Prometheus Adapter deployment is running, healthy, and accessible over TLS on port 6443. If certificate verification fails between the API aggregator and the adapter, custom metric queries will fail immediately with connection refused errors.
Once you confirm API service health, query the raw custom metrics endpoint directly using kubectl to verify metric exposure:
kubectl get --raw "/apis/custom.metrics.k8s.io/v1beta1/namespaces/production/pods/*/http_requests_per_second" | jq .
If this command returns an empty item list, the Prometheus Adapter can't find matching metric series in Prometheus that satisfy your rule's seriesQuery and label criteria. Verify that your application pods export the metric with exact label keys like kubernetes_pod_name or pod. Common Prometheus scraping setups using ServiceMonitors often rename pod labels to pod_name or instance. If label keys don't match your adapter rule overrides, the adapter can't associate time-series data with Kubernetes pod resources, causing empty API query responses.
Inspect the status conditions section of your HPA resource using kubectl describe hpa api-service-hpa -n production. The command output includes a detailed event log and active conditions like AbleToScale, ScalingActive, and ScalingLimited. If ScalingActive shows False with reason FailedGetResourceMetric, review your Prometheus Adapter pod logs using kubectl logs -n monitoring -l app.kubernetes.io/name=prometheus-adapter. Look for explicit PromQL syntax errors, HTTP timeout warnings when connecting to Prometheus, or standard authentication failures.
Common operational failure modes and their root cause solutions include:
| Observed HPA Error Message | Root Cause Mechanism | Remediation Step |
|---|---|---|
unable to fetch metric: no metrics returned | Label key mismatch between adapter rule and Prometheus TSDB | Update seriesQuery label overrides to match scraped pod labels |
selector missing from metric | Missing pod resource mapping in Prometheus Adapter rule | Ensure resources.overrides maps Prometheus label to pod |
API server request timeout | Prometheus server struggling under heavy PromQL query load | Optimize adapter metricsQuery or increase Prometheus resources |
invalid metric value: scalar expected | PromQL query returning vector without pod label grouping | Add by (<<.GroupBy>>) aggregation to adapter rule PromQL |
How Do You Tune HPA Scaling Behavior and Stabilization Windows?
You tune HPA scaling behavior by configuring the behavior field inside the autoscaling/v2 spec to set explicit scale-up and scale-down stabilization windows, rate limits, and step sizing policies. By default, the HPA controller scales up quickly when metric thresholds are breached but waits five minutes before executing scale-down actions to prevent rapid fluctuation. Customizing these stabilization windows ensures rapid scaling response during sudden traffic spikes while preventing premature pod termination during temporary traffic lulls.
The behavior section gives system engineers granular control over scaling velocity in both directions using scaleUp and scaleDown policy blocks. Each block supports a stabilizationWindowSeconds setting alongside an array of explicit policies. The stabilizationWindowSeconds causes the autoscaler to retain past calculated recommendations for a set duration, picking the highest recommendation for scale-up operations and the lowest recommendation for scale-down operations. This algorithm smooths out metric noise caused by bursty background tasks or short-lived traffic spikes.
Here's an advanced behavior configuration that enables aggressive scaling up while applying conservative scaling down:
spec:
  behavior:
    scaleUp:
      stabilizationWindowSeconds: 0
      selectPolicy: Max
      policies:
        - type: Percent
          value: 100
          periodSeconds: 15
        - type: Pods
          value: 4
          periodSeconds: 15
    scaleDown:
      stabilizationWindowSeconds: 300
      selectPolicy: Min
      policies:
        - type: Percent
          value: 10
          periodSeconds: 60
In this production configuration, setting stabilizationWindowSeconds: 0 for scaleUp instructs the autoscaler to respond immediately to metric spikes without waiting for metric smoothing. The selectPolicy: Max directive ensures that if both policies are evaluated, the policy generating the higher pod count takes effect. The HPA can double the replica count (100% increase) or add up to 4 pods every 15 seconds, whichever is larger. This prevents pod capacity exhaustion when unexpected client traffic hits your production endpoints.
Conversely, the scaleDown configuration sets stabilizationWindowSeconds: 300 (five minutes) to guarantee that traffic volume remains consistently low before terminating pods. The scale-down velocity is strictly capped at 10% of existing replica count per minute (periodSeconds: 60). Slowing down pod termination prevents cascading overload scenarios where terminating pods forces remaining pods to handle excess traffic, triggering immediate re-scale cycles.
When tuning scaling behavior, you must also align Prometheus scraping intervals with your HPA evaluation loop. If Prometheus scrapes metrics every thirty seconds but your adapter calculates two-minute rate averages, short traffic bursts under thirty seconds might fail to trigger scaling actions. Ensure your application scrapers run every ten to fifteen seconds for high-frequency scaling workloads, and configure your adapter PromQL rate windows to cover at least four scrape intervals to prevent transient metric dropouts.
How Do You Monitor HPA Performance Metrics in Production Grafana Dashboards?
You monitor HPA performance metrics in production Grafana dashboards by tracking kube_horizontalpodautoscaler_status_current_replicas, kube_horizontalpodautoscaler_status_desired_replicas, and custom metric target saturation levels over time. Integrating HPA telemetry into centralized dashboards allows platform engineers to identify misconfigured scaling thresholds, detect scaling oscillations, and evaluate workload capacity planning. Without dedicated dashboard visibility, scaling inefficiencies can silently degrade application response latency or inflate cloud infrastructure expenditures.
Prometheus exports Kubernetes HPA telemetry through kube-state-metrics, providing real-time visibility into autoscaler control loop decisions. Key metrics include kube_horizontalpodautoscaler_spec_min_replicas, kube_horizontalpodautoscaler_spec_max_replicas, and kube_horizontalpodautoscaler_status_desired_replicas. By plotting desired replicas against actual running pod replicas, you can measure scaling latency and identify whether container bootstrap times delay workload capacity expansion.
Here's a production PromQL expression for calculating HPA scaling headroom saturation across your cluster:
sum(kube_horizontalpodautoscaler_status_current_replicas{namespace="production"}) by (horizontalpodautoscaler)
/
sum(kube_horizontalpodautoscaler_spec_max_replicas{namespace="production"}) by (horizontalpodautoscaler) * 100
When this saturation query approaches one hundred percent, your deployment has reached its maximum replica ceiling and cannot expand further to accommodate incoming traffic spikes. Setting up Grafana alerts on high HPA saturation notifies on-call SRE teams to increase maxReplicas limits before application request latency breaches SLA boundaries.
You Might Also Like
- Prometheus Grafana Alerting and Burn Rate Design
- k6 Grafana Distributed Load Testing & performance Profiling
- Microservices Contract Testing with Pact & Node.js
- Playwright E2E Testing: 4 Rules for Zero Flaky Tests
Frequently Asked Questions
What is Kubernetes HPA?
Kubernetes Horizontal Pod Autoscaler (HPA) automatically scales the number of pod replicas in a Deployment or StatefulSet based on observed metrics. By default it scales on CPU and memory utilization, but with the custom metrics API it can scale on any Prometheus metric — HTTP request rate, queue depth, latency percentiles, or any business-level signal.
Can Kubernetes HPA scale on custom metrics instead of CPU?
Yes. HPA v2 supports three metric sources: Resource metrics (CPU/memory), Custom metrics from your own pods via the custom metrics API, and External metrics from systems outside the cluster. By installing Prometheus Adapter you bridge Prometheus PromQL queries into the Kubernetes custom metrics API so HPA can use them directly as scaling signals.
What is Prometheus Adapter and why do I need it?
Prometheus Adapter is a Kubernetes API server extension that translates Prometheus metric queries into the format the Kubernetes custom metrics API expects. Without it, HPA cannot read Prometheus metrics. You install it via Helm, define rules that map PromQL expressions to Kubernetes metric names, and reference those metric names in your HPA manifest.
How do I write a Kubernetes HPA v2 manifest for custom metrics?
Set apiVersion: autoscaling/v2 and under spec.metrics use type: Pods with pods.metric.name matching the rule you defined in Prometheus Adapter. Set pods.target.averageValue to the per-pod threshold. The HPA controller polls the custom metrics API every 15 seconds by default and adjusts replicas to keep the metric at the target average across all pods.
How do I troubleshoot HPA not scaling on custom metrics?
Run kubectl describe hpa <name> to see the current metric value and any error conditions. Common causes of failure: Prometheus Adapter not installed or misconfigured, the metric name in the HPA spec doesn't match the adapter rule name, Prometheus isn't scraping the target pod, or RBAC permissions are missing. Use kubectl get --raw "/apis/custom.metrics.k8s.io/v1beta1" to verify the metrics API is reachable and your metric is listed.
Free In-Browser Developer Tools
Clean AI CLI logs, build cron expressions, decode JWTs, and calculate chmod permissions offline.
Related Articles
High-Performance Observability with eBPF in Kubernetes: Bypassing the Sidecar Tax
Deep dive into eBPF observability in Kubernetes: eliminating Envoy sidecars, kernel probes, BPF ring buffers, and zero-code telemetry instrumentation.
Read more
Platform Engineering for AI: Architecting Infrastructure for Autonomous Agents
DevOps guide to architecting fleet-scale AI agent infrastructure: OpenTelemetry tracing, Firecracker execution sandboxes, state machines, and cost circuit breakers.
Read more
Implementing Zero-Trust Security in Kubernetes: The Complete Production Guide
Practical guide to eliminating flat-network perimeter security in Kubernetes: default-deny NetworkPolicies, SPIFFE/SPIRE workload identity, and strict mTLS.
Read more